Design an A/B test that answers the shipping decision
A step-by-step guide to design A/B tests that map directly to the single shipping choice you must make under tight time, sample and stakeholder limits.
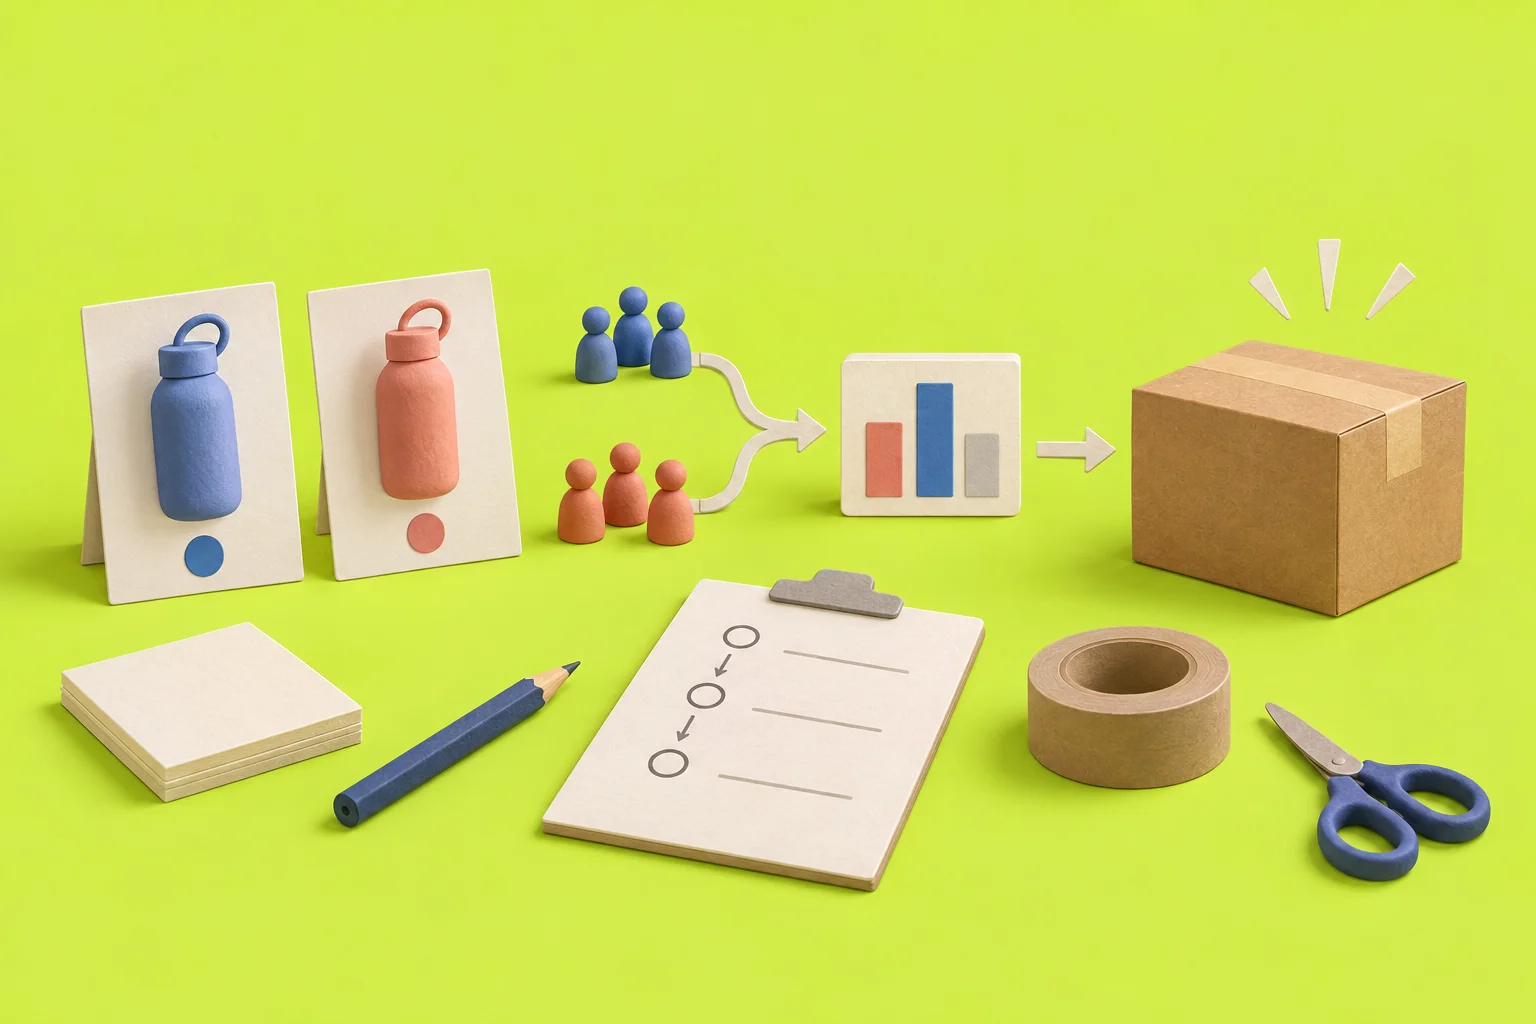
Who this is for: product managers running A/B tests with limited users, a fixed launch date, cohort seasonality or legal restrictions. What you'll have at the end: a short, prespecified test plan that maps every possible outcome to one clear shipping action.
1. Start from the decision and the acceptable error
Write the decision statement
State the single shipping choice you'll make at the review. Example: "At product review we will either change the CTA globally, run a pilot limited to sales-led accounts, or stop and run a new experiment." Keep it short and actionable.
Map outcomes to actions
For each possible test result define the precise action. Pair outcomes with which error you tolerate. Which mistake costs more: shipping a false positive or missing a real improvement?
Record this on a Hypothesis card before the test begins. Include the decision statement and the asymmetric cost of false positives vs false negatives. That will keep conversations about trade-offs focused.
2. Design the metric hierarchy
Use three levels: primary decision metric, guardrail metrics, and mechanism metrics. Document all three up front.
Primary decision metric
Pick the one metric that maps directly to your decision. It must be measurable within the test horizon and sensitive enough to show meaningful change for the action you will take.
Guardrails
These protect against shipping harms. Examples: activation rate, error rates, or revenue per user. If a guardrail breaks, the global ship option is off the table regardless of the primary metric.
Mechanism metrics
Metrics that explain why the primary metric moved: click-through on the CTA, time on trial form, step completion. They guide the iterate-or-pilot choice.
3. Constrain the test to fit the calendar
Under tight time and sample limits you must narrow the test so it answers the shipping question before the decision meeting.
- Choose the shortest valid horizon that captures the primary metric.
- Use the smallest segments that match rollout options (e.g., sales-led accounts versus self-serve).
- Pre-specify checkpoints and a final decision date tied to stakeholder reviews.
4. Allocation-aware analysis
Plan for the actual allocation and randomisation constraints you must use.
- If you must favour one arm in rollout, plan unequal allocation and set your analysis to account for it.
- Use blocked randomisation by business cohort when cohorts have different behaviours. Analyse results within blocks and in aggregate with the planned weighting.
- Prespecify subgroup checks that match your rollout levers (for example: pilot only sales-led accounts if the signal is present there).
5. Predefine post-test actions
List exactly what you will do for each quadrant of outcomes: primary metric up or down, guardrails passed or failed, mechanism signals strong or unclear.
| Observed outcome | Action | Why |
|---|---|---|
| Primary up, guardrails pass | Ship globally | Direct mapping to decision metric and no safety concerns |
| Primary up only in a business cohort | Pilot that cohort (staggered rollout) | Proof of concept where effect exists; protects against heterogeneity |
| No lift but mechanism improves | Iterate and run A/B/n on follow-up changes | Mechanism shows promise but not enough impact yet |
| No lift, no mechanism | Stop and redesign | Low signal; avoid costly rollout |
Checklist before you launch
- Decision statement and error costs documented on the Hypothesis card.
- Primary metric, guardrails, mechanism metrics specified and testable in horizon.
- Allocation and blocking plan agreed with analytics and engineering.
- Pre-specified checkpoints and stopping rules tied to the decision date.
- Stakeholders agreed they will not change hypotheses mid-test.
Worked example: a 4-week B2B trial-flow test
Context: SaaS product with a 'Start Free Trial' CTA. You have a product review in four weeks. Your choices at review: change the CTA globally, pilot to sales-led accounts only, or run a new experiment.
Decision statement
At the four-week review we will either: 1) replace the CTA across all traffic, 2) run a pilot limited to sales-led accounts, or 3) stop and design a follow-up A/B/n test. We will prefer pilot over global ship if the effect is concentrated in sales-led cohorts.
Metrics
Primary metric: trial start rate within seven days of exposure. Guardrails: trial form error rate and support ticket volume per trial. Mechanism metrics: CTA click-through, trial form abandonment, time on trial page.
Allocation and horizon
Horizon: 4 weeks, with the primary metric measured at seven days after exposure for each user. Randomisation: blocked by account type (sales-led vs self-serve). Allocation: 50/50 globally, but analysis prespecified to inspect sales-led block separately because a pilot is an available action.
Checkpoints and stopping rules
Two checkpoints: an internal check at week 2 for data quality only, and the final review at week 4. No early stopping for significance. If guardrails fail at any point, pause and investigate; do not proceed to ship. If mechanics point strongly to a cohort effect, we will choose pilot even if the global effect is marginal.
Post-test mapping
If primary metric rises and guardrails pass across both blocks: change CTA globally. If lift appears only in sales-led block with guardrails OK there: pilot sales-led accounts. If no lift but CTA click-through rises noticeably with form abandonment up: iterate on the form and run a follow-up A/B/n. If no lift and no mechanism signal: stop and re-evaluate hypothesis.
Common mistakes to avoid
- Testing many metrics without predefined decision rules. Pick one decision metric.
- Stopping for early p-values. Tie your stopping rules to the decision calendar and error costs.
- Ignoring allocation imbalance by cohort. Analyse by the blocks you used to randomise.
- Letting stakeholders change the hypothesis mid-test. Lock changes until the planned review.
- Conflating short-term activation lifts with long-term revenue. Use guardrails and mechanism metrics to surface this risk.
The pattern is simple: start with the decision, make your metrics and checkpoints serve that decision, then constrain the design so it fits your calendar and sample. A clear, prespecified plan turns noisy test results into a single shipping action.