When the A/B winner hurts some users
A story about a thumbnail-art experiment that showed why average lift hides divergent effects across devices, tenure and genres.
We ran a thumbnail-art personalization experiment like the ones you read about. The headline number showed a small average uplift. But the story underneath was mixed. Some cohorts gained a lot. Others lost. We almost shipped the wrong change.
In brief
The experiment — what we tested
Experiment design
| Variant | What it changes | Why it matters |
|---|---|---|
| Control | No change to artwork ranking | Baseline behaviour |
| Global artwork | Single artwork chosen per title for everyone | Simpler, easy to serve but ignores member signal |
| Personalization layer | Per-member ranked artwork using profile and context | Targets choices to each member and device |
What we measured, in order
- Unit: member-level assignment so each person always saw the same variant across devices when possible.
- Immediate metrics: click-through to detail page and play starts.
- Cohort signals: device type, new vs returning member, and content genre.
- Downstream: session length, next-day retention and cross-content viewing patterns instrumented as events.
What happened — the story
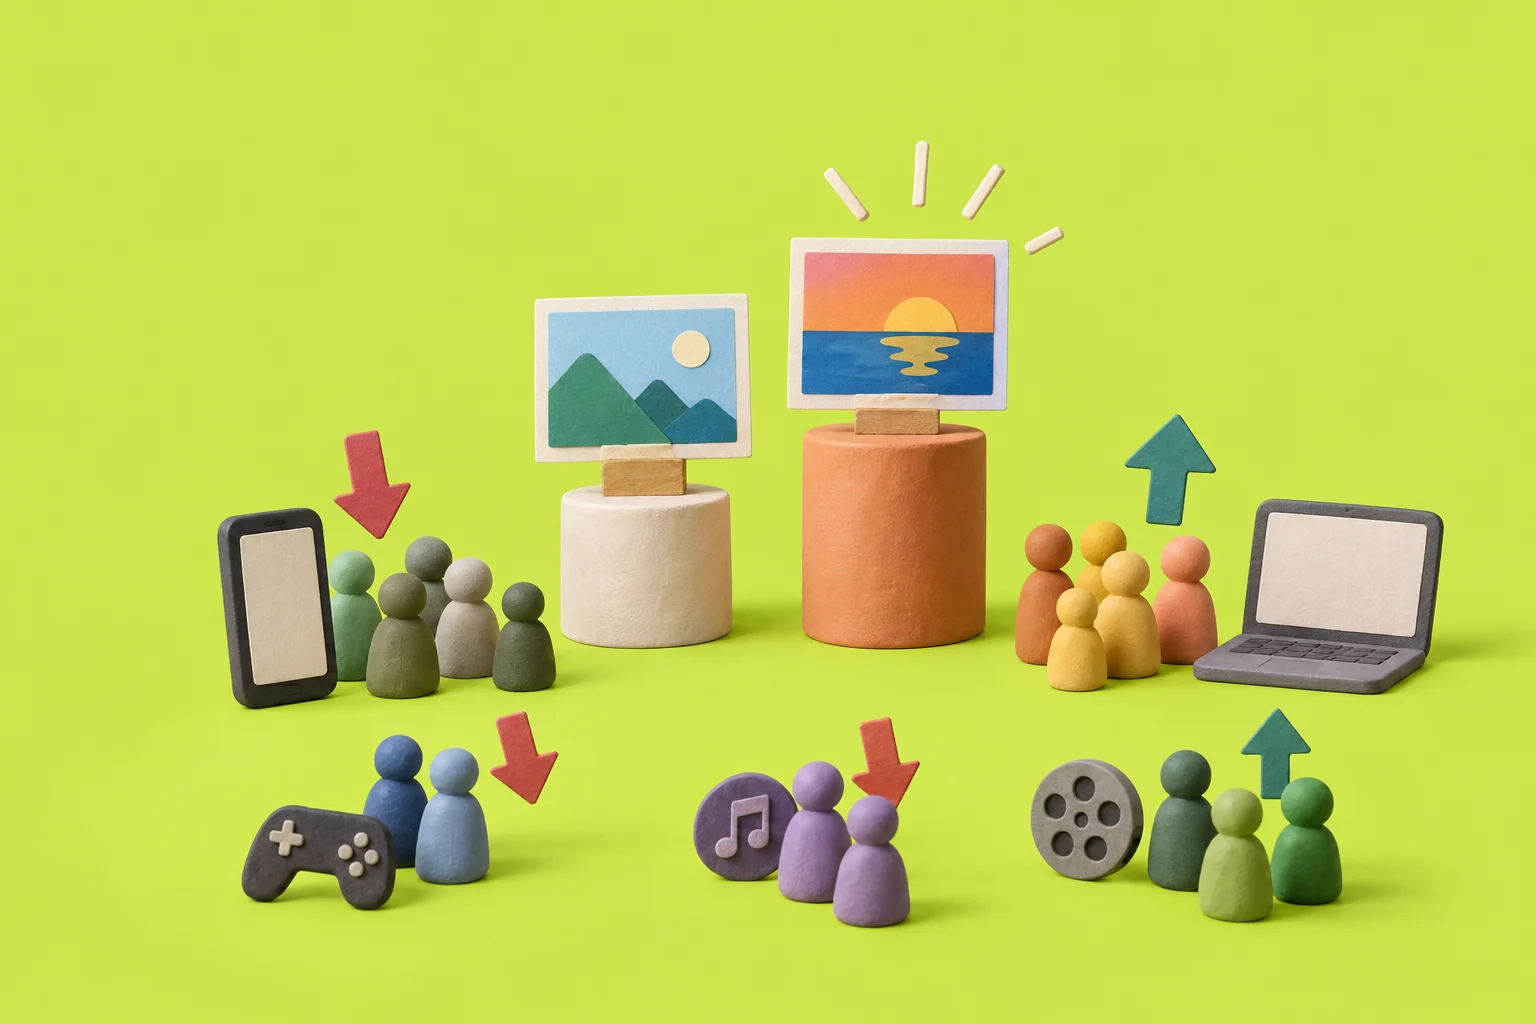
On average the personalization layer beat control by a small margin. The global artwork was neutral. That average hid three divergent effects.
- Mobile users saw bigger gains with personalization. They are quick to browse and react to precise artwork.
- New members clicked more on the global artwork in some genres. That suggested a clearer single message can help first impressions.
- On living-room devices personalization nudged cross-content behaviour in unexpected ways: members played fewer shows outside their usual genres.
How we decided what to ship
Checklist — common mistakes
- Relying on the average uplift without checking heterogenous effects.
- Ignoring sample ratio and cohort power when slicing results.
- Shipping a one-size-fits-all change without a fallback.
- Failing to track long-horizon retention and cross-content effects.
- Not planning rollout rules for mixed results.
Worked example — the decision flow
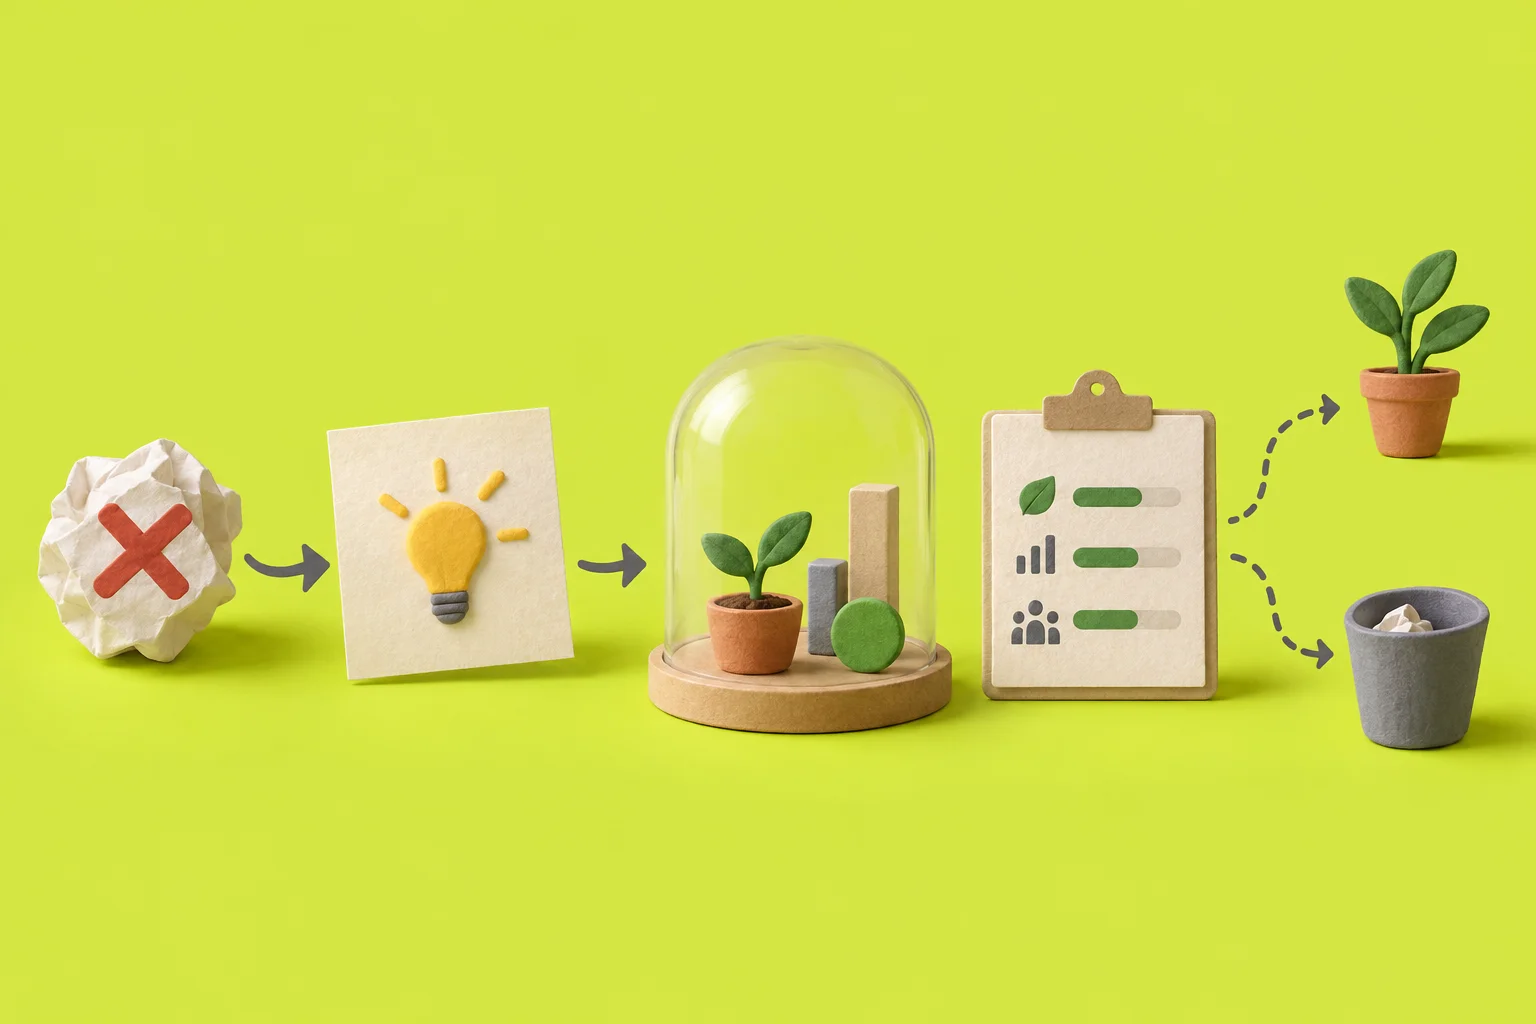
We followed a simple flow.
- Predefine cohorts: device class, member tenure bucket, primary genre interest.
- Run the three-way experiment. Assign at member level when possible.
- Compute treatment effects per cohort for immediate and downstream metrics.
- Apply rollout rules: if personalization wins on mobile and returning members, enable it there; if global artwork wins on new members for a genre, keep global there.
- Monitor retention and discovery signals for four weeks after rollout and be ready to roll back or adjust rules.
If you test personalization, name the cohorts up front. Measure heterogenous treatment effects, not only the mean. Build rollout rules that tie to those cohort signals. And keep an eye on downstream outcomes.
When you write the experiment hypothesis, capture these decisions in a Hypothesis card so the team agrees on units, cohorts and rollout criteria before you launch.