Double‑Read Your Metrics: A Practical PM Guide
Borrow radiology’s double‑read and discrepancy conferences to cut metric noise, log disagreements, and turn patterns into clear OKRs and fixes.
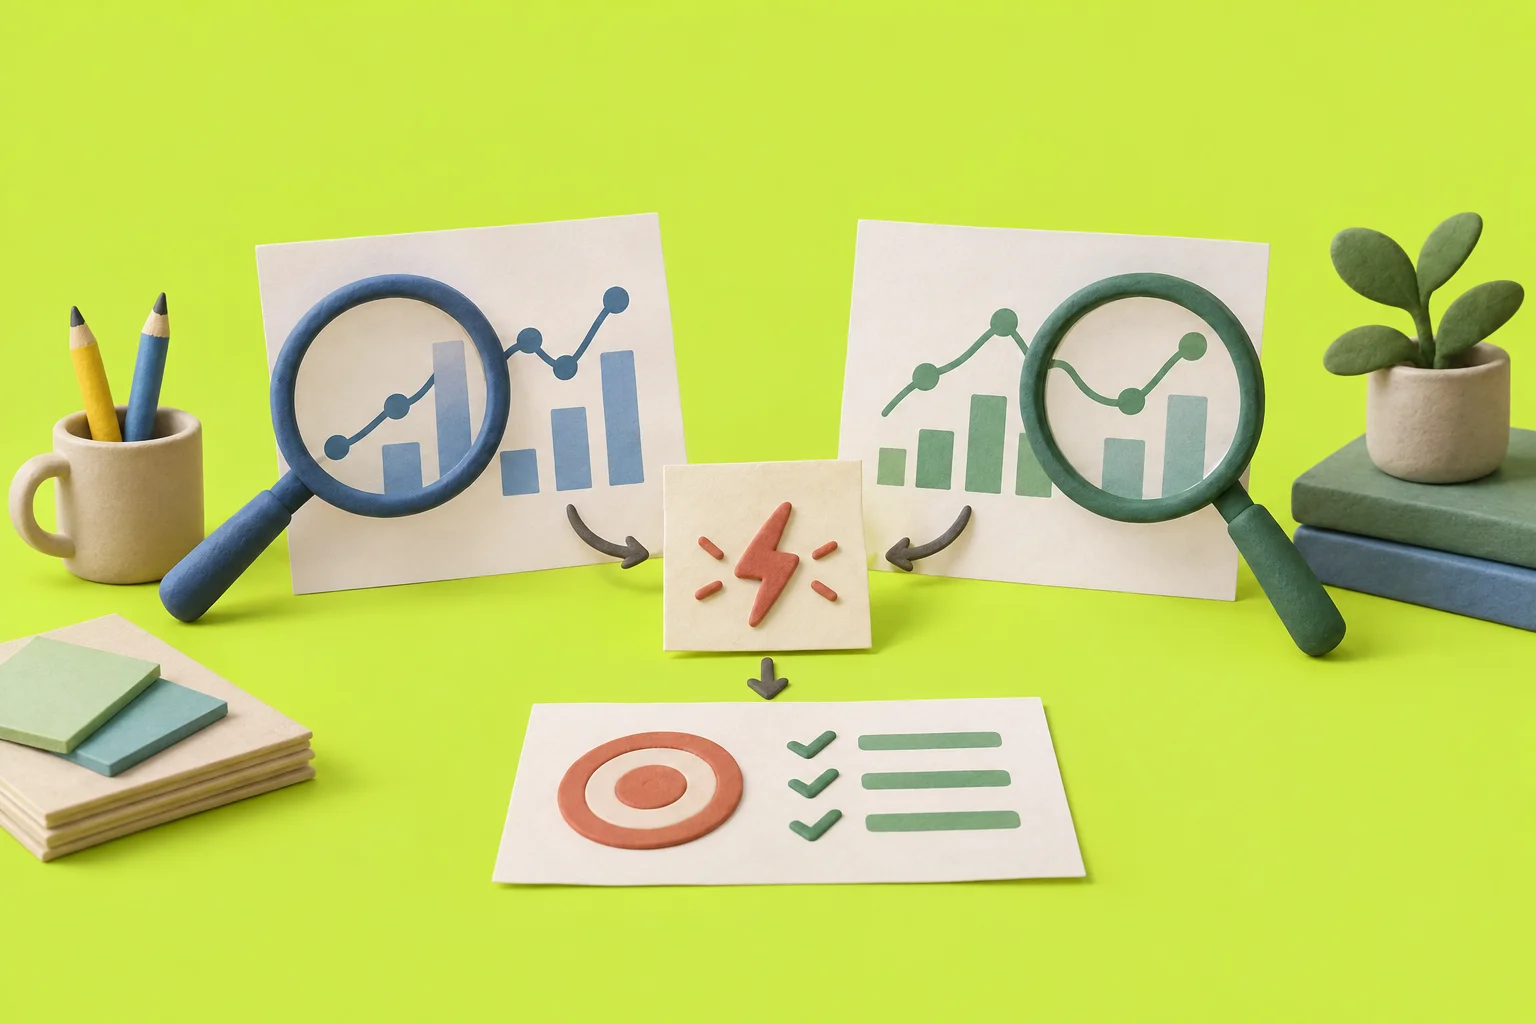
Dashboards throw up anomalies. Some are noise. Some are real. The hard part is knowing which is which before the team jumps. Radiology solved a similar problem: two reads on important scans, log disagreements, and meet to learn from patterns. We can borrow that for metrics, experiments, and outcome OKRs.
- Give top metrics a double‑read before action.
- Log each disagreement with a clear cause tag.
- Review patterns monthly and turn them into work.
- Blind the second read to cut story bias.
PMs who own metrics, experiments, or outcome OKRs and want fewer false alarms, fewer hidden failures, and clearer next steps. By the end you will have a simple double‑read workflow, a discrepancy log with useful categories, and a monthly review that feeds real decisions.
Why borrow from radiology
A single read is fast, but fragile. A double‑read slows the first move, then speeds the right one. When two people review an important alert, you reduce noise and surface bias. When you log disagreements with causes, you create a data set you can learn from. A monthly conference turns one‑off fires into system fixes.
Single‑read vs double‑read: what changes
| Aspect | Single‑read | Double‑read + discrepancy log |
|---|---|---|
| Action on alerts | Immediate, based on first view. | Held until second review confirms or flags an issue. |
| Bias control | Team story shapes the read. | Second read is blinded to the story when possible. |
| Error learning | Few records; same mistakes repeat. | Each disagreement logged with cause and confidence. |
| System fixes | Ad‑hoc tickets. | Monthly review converts patterns into priorities. |
| Team trust | Whiplash from false alarms. | Fewer reversals; clearer decisions. |
The steps, in order
Pick the top five metrics
Choose the few metrics where a wrong call hurts. Think activation, retention, revenue, key funnel rates, and experiment primary outcomes. These get a double‑read on alerts and major shifts.
Define a discrepancy taxonomy
Use simple cause tags: data, instrumentation, definition, behavior, model, seasonality. Add a short note and confidence score. Keep the list stable so patterns show up.
Automate alert metadata
Every alert should include window, baseline, segments that moved, detection method, and recent deploys. This lets reviewers work fast without digging before they decide.
Set up the double‑read
First analyst triages. Second reviewer is independent and blinded to the team narrative. Both mark cause tag and confidence. If they disagree, log it as a discrepancy.
Schedule a monthly conference
One hour. Review the last month’s discrepancies. Cluster by cause. Pull out the top recurring types. Decide which need instrumentation work and which need product work.
Tie patterns to goals
Turn the few big recurring causes into explicit work. Track product outcomes and fixes as OKRs. Track instrumentation and definition clean‑ups as planned backlog with owners and dates.
Worked example: activation funnel surge
Scenario. The activation funnel shows a sudden lift in the step from sign‑up to first action.
- Automated alert. The system flags a 25% lift vs baseline over 24 hours, names the segment that moved, and notes a recent homepage change.
- First triage. Analyst A checks data freshness, event counts, and sampling. No gaps. They tentatively mark behavior, medium confidence, and note the homepage tweak.
- Blinded second read. Reviewer B sees only the alert, the window, segments, baseline, and deploy list. No team narrative. They replay event sequences and look for spikes in a single UTM source. They mark instrumentation, low confidence, and write: “possible duplicate event on mobile.”
- Discrepancy logged. Cause tags disagree (behavior vs instrumentation). Confidence is not high. The team freezes any product decision linked to the surge.
- Fast check. Engineer checks the mobile analytics SDK. A recent update started sending a first‑action event twice for some devices. Root cause: instrumentation.
- Actions. Open a fix ticket. Backfill the event if possible. Mark the alert as a false positive due to instrumentation. Update the discrepancy log with final cause.
- If both had confirmed behavior. The team would frame a simple experiment on the homepage change and set an outcome target as an experiment OKR.
What to include in each discrepancy record
- Metric and segment affected.
- Alert window and baseline.
- Reviewer A and B cause tags and confidence.
- Notes in one or two lines each.
- Final cause after resolution.
- Decision taken: proceed, pause, or fix data first.
Blinding that actually helps
Do not hide the numbers. Hide the story. Show the anomaly, the time window, the segments, the detection method, and the deploy list. Hide the team’s hypothesis and any slides that argue a position. For hypothesis tests, blind the variant labels if you can. The goal is a second opinion, not a second voice in the same echo.
- Activation and retention steps.
- Revenue or conversion rates that steer spend.
- Primary experiment outcomes.
- Metrics used in leadership updates.
Run the monthly discrepancy conference
- Prepare: export the month’s discrepancies. Group by cause and by metric.
- Open: state the goal — learn and improve the system. No blame.
- Review clusters: where did we disagree most and why.
- Decide fixes: definitions to lock, dashboards to adjust, alerts to tune, instrumentation to repair.
- Promote a few into near‑term priorities. Assign owners and dates. Track product and measurement goals alongside delivery.
Mistakes to avoid
- Turning reviews into bureaucracy. Keep it to the top five metrics and primary outcomes.
- Relying on one reviewer. Rotate the second read across analysts or PMs.
- Ignoring low‑confidence disagreements. They are often where you learn.
- Letting the conference become a blame forum. Focus on system fixes.
- Failing to act on patterns. Convert repeats into changes or tracked goals.
Your first week plan
- List your top five metrics and add them to the double‑read list.
- Adopt the six cause tags and a 3‑level confidence scale.
- Update alert templates with the key metadata.
- Pick three people to rotate second reads.
- Put a 60‑minute monthly discrepancy conference on the calendar.
- Decide how you will track the few resulting goals alongside product work.
Why this works
You treat anomalies as diagnostic problems, not tickets. You get a second opinion before action. You learn from disagreements. You fix the system where it leaks. Over time, alerts get cleaner, metrics get easier to trust, and decisions get faster because they rest on a shared ritual.