Launch buckets: a repeatable GTM pattern for features
Design and run launch buckets to learn product, price, and messaging at once, with clear rules, metrics, and decision points.
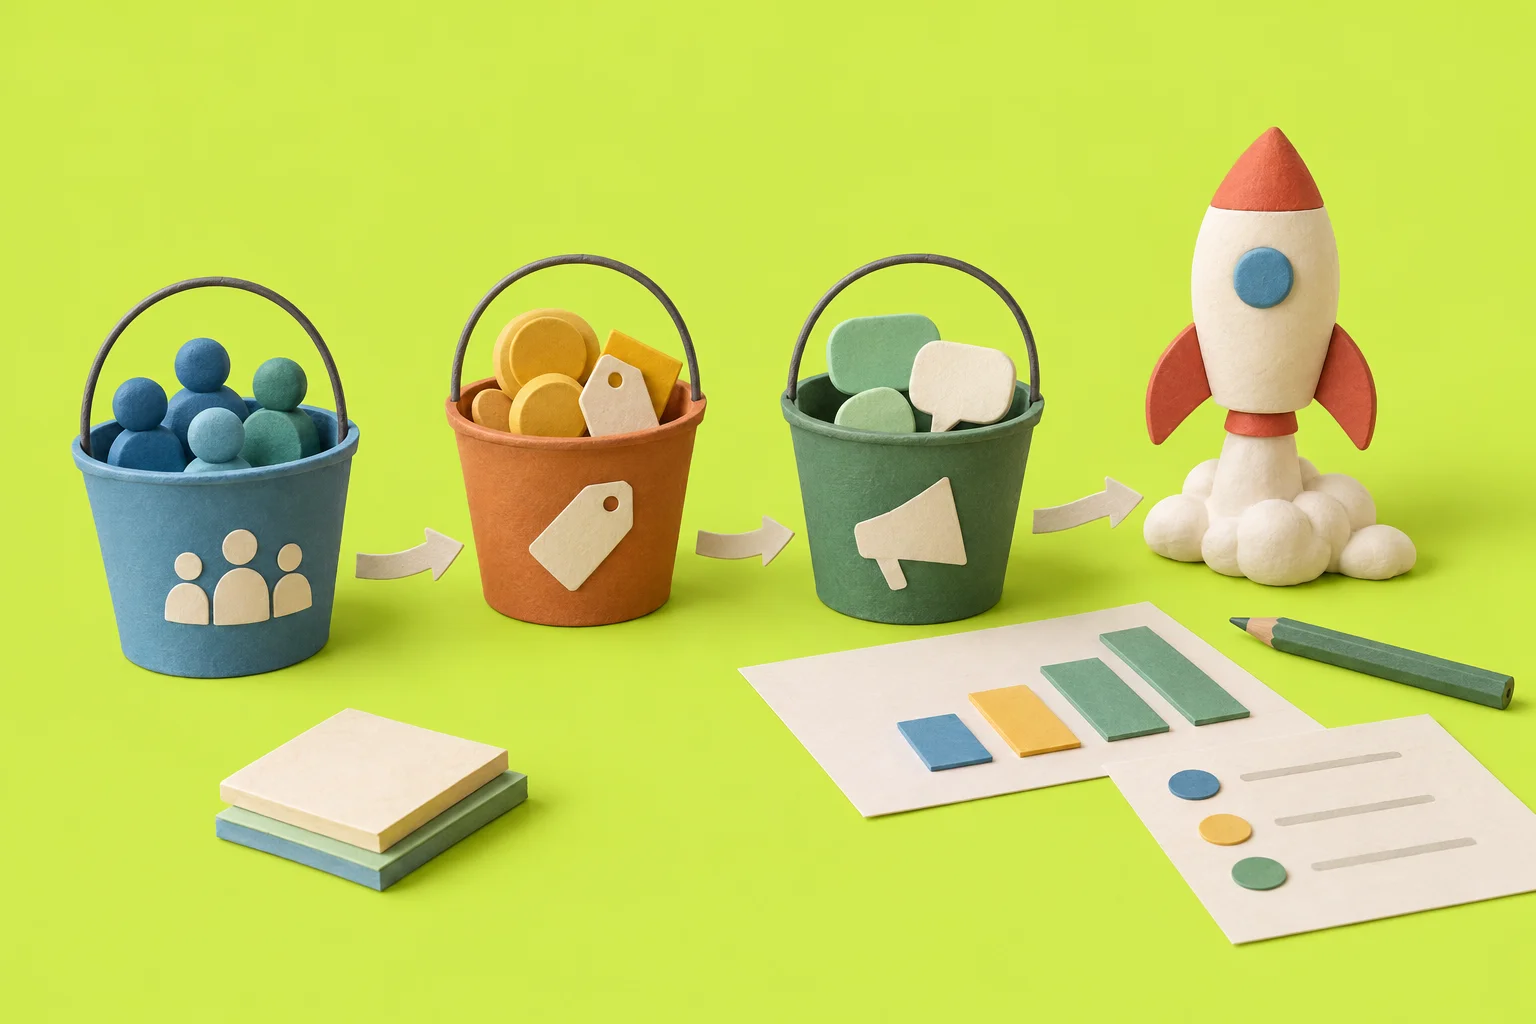
Traditional staged rollouts blur product, price, and messaging. You ship a beta, then a slow ramp, then full. You learn something, but not what to scale or how to price. Launch buckets fix this. You split customers into clear groups, each with its own product access, price signal, and message. You run them at the same time with rules and metrics. You get clean answers fast, with low risk.
In brief
Who this is for
Working PMs who want a repeatable GTM pattern that avoids all-or-nothing launches.
What you get
- Bucket definitions and hypotheses
- Primary and guardrail metrics
- Team playbooks and comms
- Decision dates and rules
When to use
When a feature could be premium, metered, or free, and you must learn product, price, and message at once.
What is different
Simultaneous, orthogonal experiments. Clean signals by bucket. Product + price + messaging tested together.
Buckets are simultaneous, not sequential. Each has its own product, price, and message.Run them in parallel with explicit rules and a single primary metric per bucket.
Why launch buckets beat staged rollouts
| Staged rollout | Launch buckets |
|---|---|
| One path for all users over time | Separate customer groups run in parallel |
| Mixes product, price, and comms changes | Orthogonal tests: product, price, and message set per bucket |
| Hard to attribute effect | Clean comparison across buckets |
| Slow to learn pricing | Price signal from day one in at least one bucket |
| Vague decision points | Pre-set thresholds and dates per bucket |
The steps
Set the outcome and guardrails
- Pick 1–2 primary business outcomes (e.g., new paid accounts, retention uplift).
- List hard guardrails: unit cost, abuse rate, support load, latency, error rate.
- Agree on a short test window (e.g., 2–4 weeks) and a decision date now.
Define buckets
- Make 2–4 mutually exclusive customer groups.
- Give each: eligibility, assignment method, product access, price/meter, and message.
- Include at least one bucket with a real price signal.
Write a hypothesis card per bucket
- Hypothesis: what will change and by how much.
- Primary metric: the one number that drives the decision.
- Secondary metrics: adoption, usage, conversion; list but do not optimize to them.
Set operational rules
- Eligibility: who can be in each bucket and who is excluded.
- Assignment: randomization keys, stratification, and holdouts.
- Duration: fixed start and end; no mid-flight changes.
- Kill/succeed criteria: thresholds that force an action.
Align sales, CS, and marketing
- One-page playbook per bucket: pitch, objections, offers.
- Comms templates: emails, in-product copy, support macros.
- Agree what not to do: no cross-bucket discounts or exceptions.
Instrument metrics and queries
- Tag every event with bucket id and assignment timestamp.
- Build daily queries for primary and guardrail metrics.
- Set alerts for guardrails: cost spikes, abuse, error rates.
Dry run and launch
- Run a sandbox with test users per bucket.
- Send test comms; confirm routing and macros.
- Freeze eligibility rules; publish the decision calendar.
Monitor and decide
- Review metrics on a fixed cadence.
- Hold the decision meeting on the set date.
- Apply scale or rollback rules as written. No edits post hoc.
Deliverables checklist
- Bucket definitions (eligibility, assignment, product, price, messaging)
- Hypothesis card per bucket (primary metric, thresholds)
- Analytics queries and dashboards with bucket tags
- Comms templates and GTM playbooks per bucket
- Rollback and scale rules with decision dates
Worked example: AI assistant premium feature
You plan to launch an AI assistant inside your product. It drafts content and answers questions. You suspect it should be a premium feature. You want to learn adoption and price sensitivity fast, while keeping cost and abuse under control.
Buckets:
Free (read-only)
EligibilityAll existing Free tier users; exclude enterprise; new signups included.
AssignmentRandom 50% of Free users; keyed by user_id modulo rule; fixed for 14 days.
ProductSee AI suggestions but cannot click to generate; CTA explains premium.
Price signalShows paid plan with price; no trial; upgrade button visible.
MessagingValue-forward: time saved; clear limits; path to upgrade.
Primary metricUpgrade rate to paid from Free users exposed.
GuardrailsLatency under target; no more than set support tickets per 1k users.
Duration14 days. No mid-flight changes.
Decision ruleScale read-only exposure if upgrade rate and CTR exceed target and guardrails hold.
Trial (14-day premium)
EligibilitySelf-serve Pro users not on enterprise contracts; exclude recent trials.
AssignmentRandom 30% of eligible Pro accounts; stratify by tenure; fixed for 14 days.
ProductFull AI access for 14 days with visible meter.
Price signalShows post-trial price and included quota; no discounts beyond listed offer.
MessagingTrial countdown, use cases, and prompts to try key flows.
Primary metricTrial-to-paid conversion by day 21 (7 days post-trial).
GuardrailsUnit cost per generated task under limit; abuse flags below threshold.
Duration14-day access; measure for 21 days total.
Decision ruleKeep trial if conversion beats threshold and cost per conversion is viable.
Paid (from day one)
EligibilityNew business signups; exclude any with negotiated pricing.
AssignmentRandom 20% of new signups; balance by channel; fixed for 21 days.
ProductFull AI access on the paid plan only; no trial.
Price signalPrice shown up front; metered overage visible; annual option offered.
MessagingPosition as a premium productivity add-on; ROI examples; no free try.
Primary metricNew paid attach rate and ARPU uplift vs. control signups.
GuardrailsRefund rate and early churn below set limits; support load manageable.
Duration21 days for new signups cohort.
Decision ruleAdopt “paid from day one” if attach and ARPU uplift exceed targets without harming early retention.
Operational rules
- Holdout: keep at least 10% of eligible users in control (no AI exposure) for baseline.
- No switching: once assigned, users stay in bucket until end of duration.
- Single source of truth: store bucket_id and assigned_at on the account and all events.
- Kill switch: pause generation if unit cost or abuse exceeds guardrail for 24 hours.
- Decision date: day 22 for Trial and Paid, day 15 for Free; calendar invites sent before launch.
Analytics plan
- Daily report by bucket: primary metric, guardrails, sample size, and confidence bands.
- Queries: upgrade rate (Free), trial start and end with conversions (Trial), attach rate and ARPU (Paid).
- Cost and abuse: cost per generated task, flagged accounts per 1k users, and rate limits hit.
- Quality: latency and error rate per 100 requests; satisfaction proxy from support tags.
GTM playbooks and comms
- Free: in-product upsell banner, onboarding tooltip, monthly email with use cases.
- Trial: start email, mid-trial nudge, 48-hour pre-expiry reminder, post-trial offer.
- Paid: pricing page copy, sales talk track, objection handling, and cancellation save macro.
- Rule: reps cannot move a user across buckets; no off-book discounts.
Decision thresholds
- Free: if upgrade rate is at or above target and click-through on AI CTAs meets target, keep read-only preview for Free.
- Trial: if trial-to-paid conversion exceeds target and blended unit economics are positive, keep trial model; else shorten or remove trial.
- Paid: if attach rate and ARPU uplift meet targets without harming week-4 retention, adopt paid-from-day-one for new signups.
Common mistakes to avoid
- Mixing signals across buckets (e.g., letting Trial users see Free messaging).
- Changing eligibility mid-experiment; it breaks your comparisons.
- Weak guardrails on cost or abuse; set alerts before launch.
- Unclear decision dates; schedule them and stick to them.
- Optimizing to secondary metrics instead of the primary one.