Prioritise when evidence conflicts: revenue, retention and tech risk
A short, repeatable process to rank revenue, retention and technical risk when evidence points different ways.
Who this is for: working product managers with limited runway and multiple stakeholders. What you'll have: a short process, a reusable table and a defensible ranked list you can update weekly.
Steps: make the job explicit, score on separate axes, and repeat
- 1Define the job-to-be-done for this decision window
- 2Convert every request into a clear, testable hypothesis
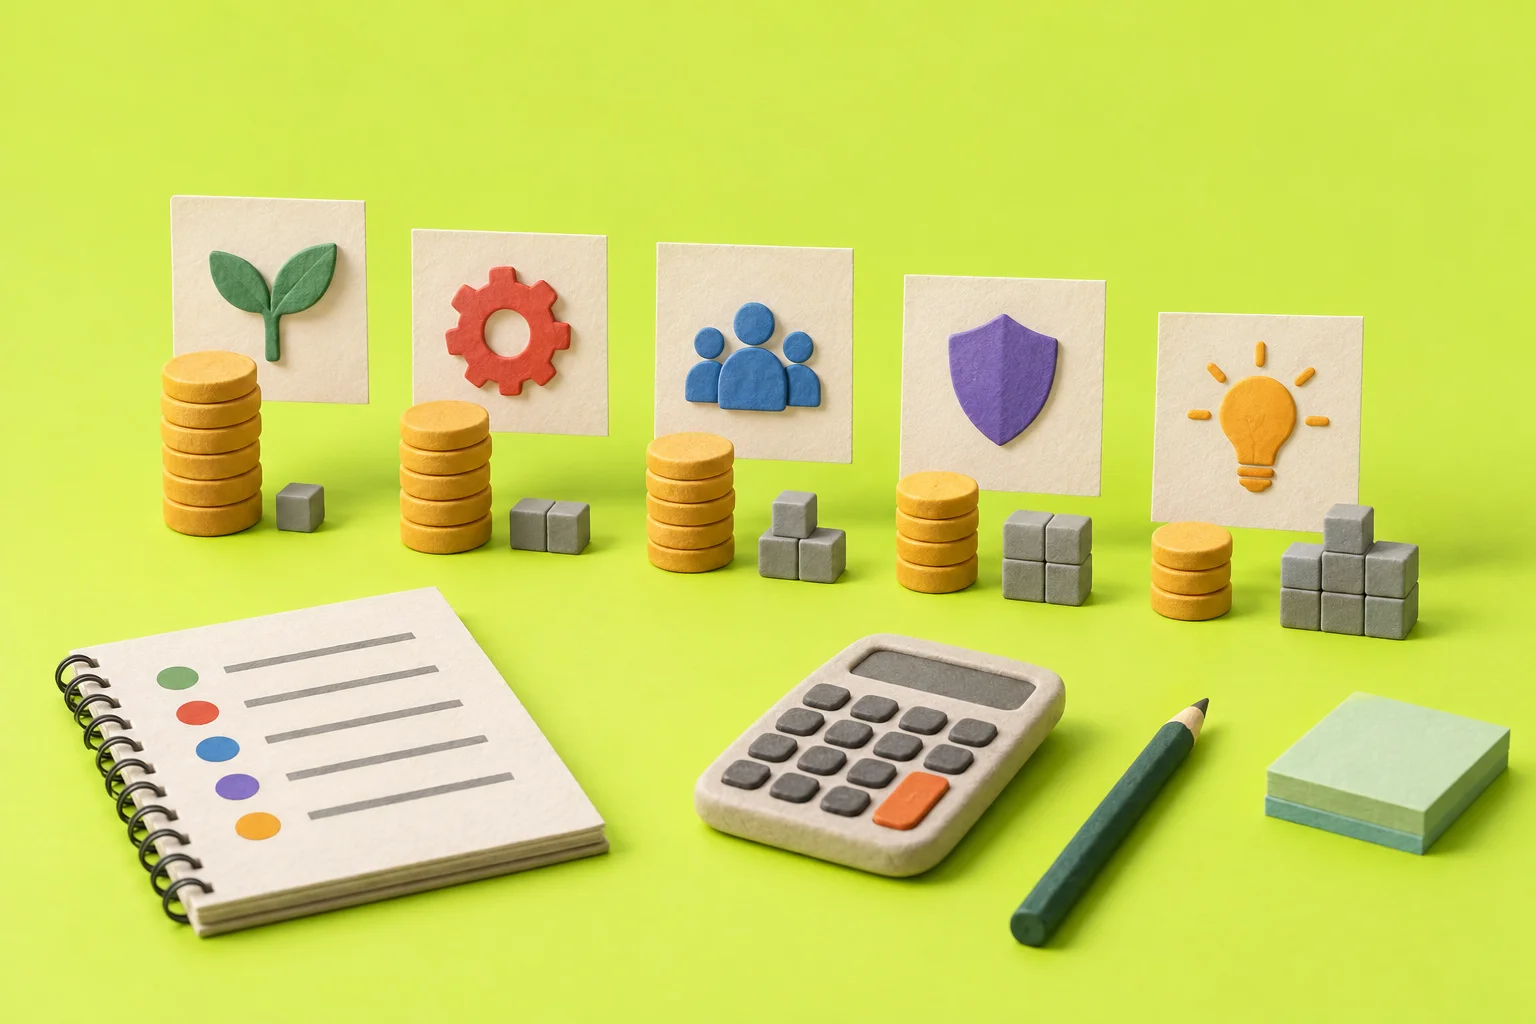
- 3Score each idea across five dimensions
- 4Apply evidence and remediation thresholds
- 5Run a short weekly cadence to update and re-rank
Why separate dimensions (and why evidence is its own axis)
Revenue, retention and technical risk are different problems. Treating them as the same score hides trade-offs. Use separate axes so you can see where an idea wins and where it is weak. Score evidence quality on its own axis: a high-revenue claim based on a single anecdote should not beat a medium-revenue claim with robust tests.
"Make the claim testable, then the scores become comparable."
How to turn asks into testable hypotheses
Ask: if we ship X, what measurable outcome changes and by how much? Write it like: "Changing A to B will increase conversion from X to Y for customer segment Z within 14 days." That makes the evidence you need obvious.
Checklist: common mistakes
- Confusing loud stakeholders with high value.
- Double-counting the same benefit across multiple dimensions.
- Using stale or anecdotal evidence as if it were fresh proof.
- Treating prioritisation as once-and-done instead of an evolving decision.
Comparison table (what to capture for each idea)
| Outcome (job) | Evidence quality (1-5) | Effort (T-shirt) | Cost of Delay (1-5) | Tech Risk (1-5) | Hypothesis | Evidence log |
|---|---|---|---|---|---|---|
| Example: paywall conversion | 3 | M | 4 | 1 | New paywall messaging will lift conversions by 8% for returning users | A/B test, n=1,200; product analytics |
Cadence and thresholds
Run a weekly micro-review. Update evidence logs and scores. If a revenue claim has evidence-quality below your minimum (for example, 3 of 5), it needs validation before it moves ahead. If tech risk scores above your remediation threshold (for example, 4 of 5), schedule remediation or a smaller mitigation spike before feature work.
Short script to explain the top three
Use the same short script for stakeholders: "We ranked items by outcome, evidence, effort, delay cost and technical risk. These three lead now because they hit the job, have the best evidence for impact, and fit our effort and risk limits this week." Keep it factual and show the evidence-log lines.
Worked example: five competing bets
Context: limited runway, one engineering squad, and these five requests. Each line shows the job, a hypothesis, scores on a 1-5 scale (or effort as S/M/L), and a brief evidence log. Pick your own numeric thresholds; here evidence >=3 is required for revenue claims and tech risk >=4 triggers remediation.
| Item | Outcome (job) | Hypothesis | Evidence | Effort | Cost of Delay | Tech Risk | Evidence log |
|---|---|---|---|---|---|---|---|
| Paywall tweak | Increase conversion | New paywall copy will increase paid conversions for returning users by 6% | 4 | S | 4 | 1 | Recent A/B test (n=1,200); analytics show lift in trial signups |
| Onboarding rewrite | Improve retention | Streamlined onboarding will reduce day-7 churn by 10% for new users | 3 | M | 3 | 2 | User interviews; event drop-off map |
| Analytics fix | Restore measurement and decisioning | Fixing missing events will restore accurate conversion metrics within 48h | 5 | S | 5 | 2 | Error logs and recent audit; conversion estimates currently unreliable |
| Bulk import | Reduce churn for large customers | Adding bulk import will reduce churn among mid-market by 8% over 30 days | 2 | L | 3 | 2 | Several support tickets and two sales asks; no validated lift |
| Critical library upgrade | Reduce outage risk | Upgrade critical library to avoid security and compatibility failures | 4 | M | 2 | 5 | Dependency audit shows end-of-life warnings and failing tests in CI |
How this ranks: first, fix analytics (evidence 5, cost of delay 5). Second, paywall tweak (high evidence, low effort). Third, onboarding rewrite (moderate evidence and impact). The library upgrade must not be ignored: tech risk is 5 so either remediate now or block shipping related features until mitigated. Bulk import waits until we gather stronger evidence.
Short script to stakeholders: "We ran each request against outcome, evidence, effort, cost of delay and tech risk. Analytics fix and paywall tweak scored highest on evidence and impact for the effort. We’ll remediate the high tech risk on the critical library before shipping related features."
Final note
Prioritisation is a short process and a living document. Use the table, require minimum evidence for revenue asks, and set a remediation trigger for high technical risk. Repeat weekly. If you need a quick place to record these columns and keep the evidence log, use the Prioritisation table and update it in your weekly micro-review.