Turn messy feedback into traceable user stories
A step-by-step guide for PMs to use AI as a synthesis engine, producing a user story, Gherkin acceptance criteria, test cases and traceable evidence.
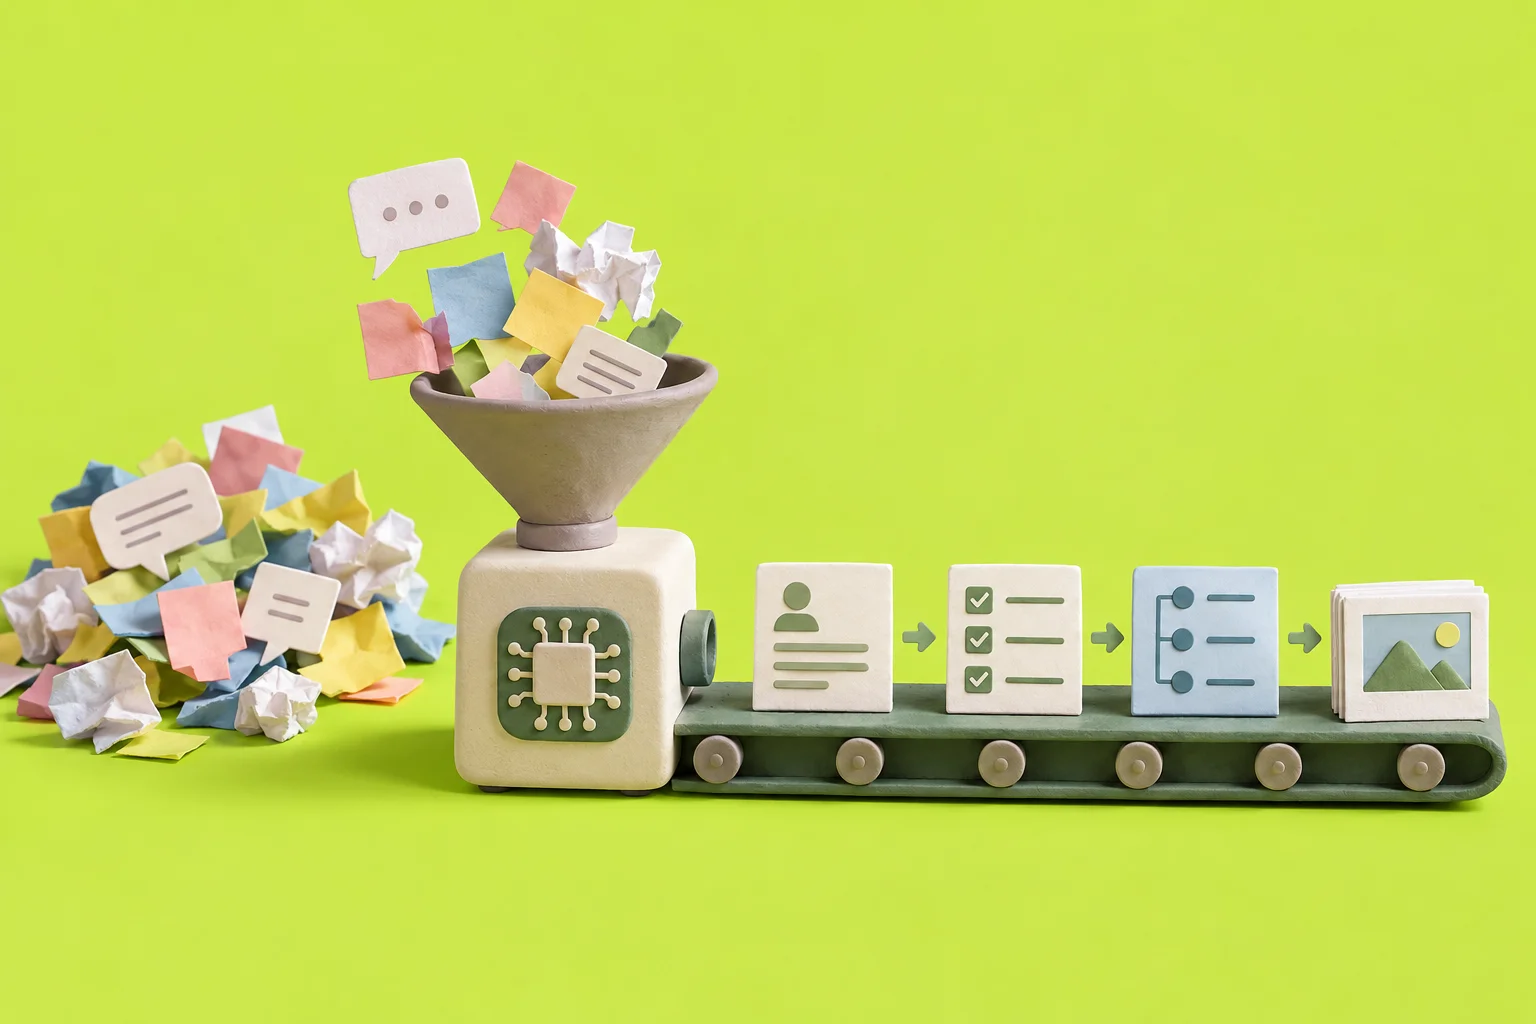
Who this is for: working PMs sitting on piles of unstructured feedback (support emails, session notes) who need ready-for-engineering user stories with traceable evidence. At the end you'll have a polished user story, Gherkin acceptance criteria, two test cases that point back to sources, a confidence map per criterion, and copyable tickets.
Use AI as a synthesis engine: feed clustered evidence and strict constraints. Run a retrieval-augmented prompt that includes exact excerpts and metadata, and ask for three artifacts in one pass: user story, Gherkin ACs, and two test cases with source links. Score confidence per AC and attach minimal quotes.
Why this matters
Unfiltered dumps make AI invent details. If the output lacks sourceable evidence, stakeholders will ask for receipts and engineers will ask for clarification. A short RAG workflow keeps AI honest and reduces rework.
Step-by-step cards
1. Cluster evidence
Group messages and notes by symptom or task. Keep counts and channels: e.g. support emails (12) mentioning "upload fails for >50MB", session replays (3) showing spinner then crash.
2. Pick canonical excerpts
Select short, verbatim excerpts that show the problem and metadata: channel, item id, and why it matters. Limit excerpts to 1–2 lines each.
3. Craft a RAG prompt template
Embed the canonical excerpts and explicit constraints. Ask for: a single user story, Gherkin acceptance criteria, two test cases, a confidence score per AC, and the minimal supporting quote(s) per criterion.
4. Run AI and validate
Check each claim against the provided excerpts. Only keep outputs that can be traced; ask for fixes where sources don’t match.
5. Convert to tickets
Copy the story, ACs and confidence map into your ticket system. Include links to the canonical excerpts so reviewers can inspect the evidence.
Quick comparison: naive dump vs RAG prompts
| What you give the model | Typical result | What to do instead |
|---|---|---|
| Full mailbox export | Long, often hallucinated story | Cluster messages; send 6–12 canonical excerpts |
| High-level summary only | Vague acceptance criteria | Include verbatim quotes and channel IDs |
| No nonfunctional constraints | Missed size/timeout edge cases | List size limits, timeouts, retry rules explicitly |
Treat the model as a synthesis engine. Require traceable claims.
Prompt template (pattern)
Worked example
Input evidence we use: 12 support emails saying uploads fail for files over 50MB; 3 session replays showing a spinner then the page/tab crashes. Canonical excerpts (selected):
AI output (edited for clarity)
All claims in the output link to the canonical excerpts. Acceptance criteria are Gherkin-ready and the confidence_map shows which criteria need more investigation.
Copyable tickets
Validation and handoff
Before assigning to engineering: run the two test cases in a staging environment and record results. If an AC has Medium/Low confidence, add a small investigation task linking to the relevant excerpts. Use a short implementation notes block to catch nonfunctional constraints early (size limits, timeouts, retries, privacy of uploaded data).
Common mistakes to avoid
- Feeding the model large unfiltered dumps.
- Omitting direct quotes or channel IDs in the evidence package.
- Accepting vague acceptance criteria without confidence labels.
- Skipping nonfunctional constraints like size, timeout and retry behaviour.
If you want a template to run this pattern in your workflow, paste the canonical excerpts and use the prompt pattern above. For writing the final story into your ticket tracker, export the "story" field and the ACs directly into a User story card.