Run a Stress Test on Activation and Growth Loops
Use a cardiology-style stress test to find hidden weaknesses in activation, retention, and growth loops. Steps, telemetry, endpoints, and a worked example.
This is for product managers who own onboarding, retention, and growth loops. You will set up a repeatable stress test that exposes weak points fast and safely. At the end you will have a protocol, a confidence map of loop resilience, a shortlist of fixes, and a runbook for the next spike.
In brief
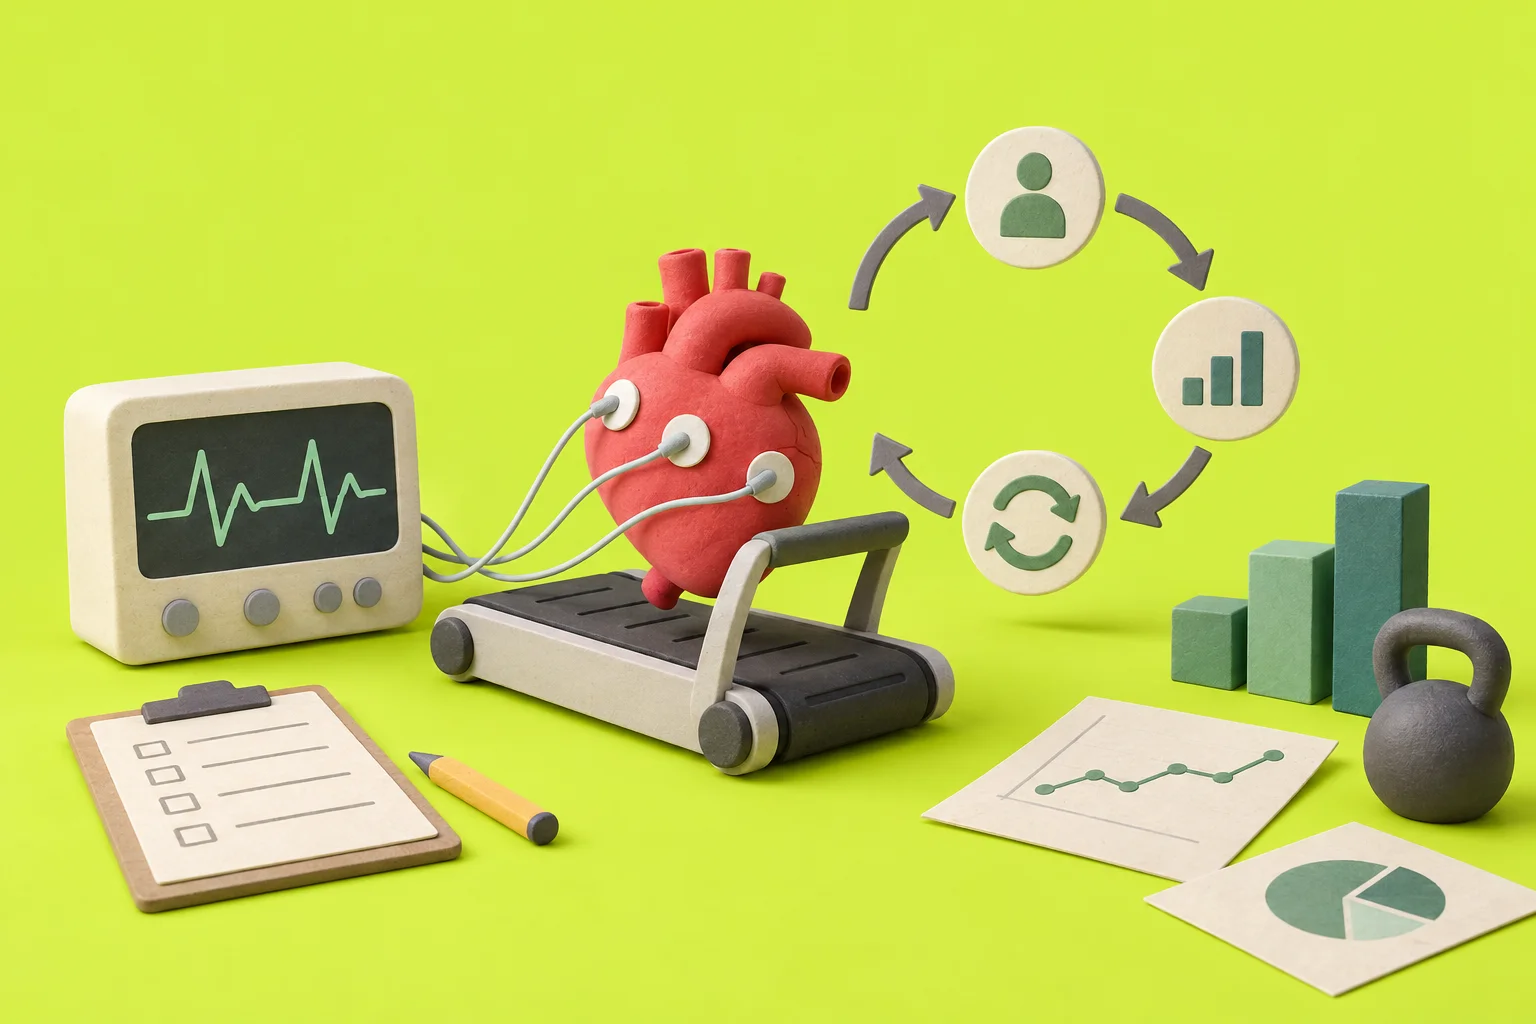
- Borrow a cardiologist’s stress test: baseline, staged load, continuous monitoring, clear stop rules.
- Map vitals to product metrics: time‑to‑value, conversion cadence, cohort drop‑off, error types.
- Design stressors: volume surges, speed of feature sequencing, edge‑case input, multi‑path use.
- Instrument short‑window signals and act on predefined endpoints with planned rollbacks.
Why a stress test, not just A/Bs
A/B experiments tell you which variant wins on average. They rarely tell you when a loop starts to fail. Growth is lumpy. Users batch actions. External traffic spikes. A cardiology stress test is built for that. It starts from rest, raises load in stages, watches vitals continuously, and stops on clear endpoints. The same structure exposes hidden thresholds in activation and retention.
You do not learn where a loop breaks until you lean on it on purpose.
Map the vitals to product metrics
| Cardiology vital | Product analogue | What to watch |
|---|---|---|
| Resting heart rate | Time‑to‑first‑value (TTFV) | Median minutes from sign‑up to first aha moment |
| Exercise intensity | Conversion cadence | Rate of step completions per minute during onboarding |
| Ischemia signal | Cohort drop‑off | Short‑window slope changes in activation or D1 retention |
| Blood pressure | Latency and queue depth | API p95, job backlog, retries |
| Arrhythmia | Error profile | Spike in specific failure types or timeouts |
| Recovery time | Loop recovery | Time to restore baseline conversion after a surge |
The protocol: steps
Set baseline
Fix today’s baseline for activation and early retention. Use a recent, clean cohort. Record TTFV, activation rate, D1/D7 retention, invite→invitee conversion, error rate, p95 latency.
Define vitals
Choose 5–7 telemetry signals you will watch continuously. Include at least one conversion slope, one latency metric, and a typed error counter. Keep windows short (1–5 minutes) for slope changes.
Plan stressors
- Volume surge: burst sign‑ups or invites.
- Sequencing speed: compress time between onboarding tasks.
- Edge‑case input: odd file sizes, long names, locale quirks.
- Multi‑path use: users branch into less common flows.
Predefine endpoints
Set stop rules and rescue actions. Example: if activation conversion drops by more than a set percent in a short window or specific errors spike, pause the stage and roll back traffic.
Capture assumptions and thresholds on a Hypothesis card.
Run staged load
Execute stages with rising load. Hold each stage long enough to see stabilization. Randomize eligible users so you can compare against a control that stays at baseline.
Debrief and prescribe
Log failure modes, root causes, and fixes. Prioritize quick wins (UI friction, async retries, rate limits) and record the confidence range where loops remain resilient.
What to monitor in real time
- Conversion slopes in short windows (1, 5, 15 minutes) for key steps.
- Micro‑retention: percent returning within 24 hours after first value.
- Error types and sources: client vs server, timeouts vs validation.
- Queue depth and retry rates in background jobs.
- API p95/p99 latency and timeouts at known choke points.
- Backpressure triggers: rate limits, captcha, or wait rooms engaged.
- Recovery: how fast signals return to baseline after load drops.
Endpoints and rescue plans
Decide before the test how you will stop and what you will do. Keep criteria simple and visible to everyone in the room.
- Stop if activation conversion drops by a set percent within a set number of minutes.
- Stop if typed errors pass a ceiling per minute or a new error appears.
- Stop if p95 latency at a critical step exceeds a ceiling for more than a short window.
- Rescue actions: roll back traffic to last stable stage, divert to control, enable rate limits, or deploy a safe hotfix experiment.
A/B vs stress test: when to use which
| Question | A/B test | Stress test |
|---|---|---|
| Which variant wins on average? | Good | Not the goal |
| Where are failure thresholds? | Weak | Strong |
| How do loops interact under load? | Limited | Direct |
| Risk control and rollback | Basic | Built‑in endpoints |
| Time to insight on hidden modes | Slow | Fast |
Readiness and safety checklist
Before you run
- Randomization in place; control cohort untouched by stress.
- Segments and sample sizes planned; power checked for primary metrics.
- Clear stop rules and rescue playbook written and agreed.
- Rate limits, queues, and fallbacks tested in a dry run.
- Observability: dashboards for short‑window metrics ready.
- Stakeholder notice for possible user impact; support on standby.
- Data logging for failure types; time‑boxed stages with owners.
Worked example: SaaS onboarding + referral loop
Goal: probe how onboarding holds up when user actions bunch and invites flow back into the top of the funnel.
Baseline
Run standard onboarding with current pacing. Record TTFV, activation rate, D1/D7 retention, invite→invitee conversion, and error rate. This is your resting state.
Faster sequencing
Shorten delays between steps. Reduce guidance modals and nudge users to complete the next task immediately. Watch conversion slope and TTFV. Look for UX friction and validation errors.
Concurrent invites
Allow users to send invites while finishing setup. This makes two loops run at once. Monitor queue depth, email/API latencies, and typed errors in invite creation and acceptance.
High acceptance burst
Simulate or drive a burst of invite acceptances (e.g., scheduled campaigns). Track invite→invitee conversion, activation for invitees, and any backpressure triggers. Measure recovery time after the burst.
Stop criteria: if activation conversion falls more than 10% in a short window or if errors spike above your ceiling, stop the stage and roll back traffic to the last stable state.
What to capture during each stage:
- TTFV median and distribution shifts.
- Activation rate and short‑window conversion slope.
- D1/D7 retention for new users and invitees.
- Invite→invitee conversion and time to accept.
- Error profile changes and where they occur in the flow.
Likely prescriptions if failure appears:
- UI friction: trim optional steps, prefill defaults, defer heavy tasks.
- Async retries: make outbound calls idempotent; backoff on failure.
- Rate limits: cap invites per minute per user; queue with clear feedback.
- Operational: warm caches before campaigns; isolate invite processing from onboarding state updates.
Common mistakes to avoid
- Skipping randomization and mixing in confounds.
- Ignoring segment differences and running under‑powered tests.
- Pushing load too far and causing real churn; respect endpoints.
- Reading transient noise as structural failure; check recovery.
- Starting without a rescue plan; rollbacks must be one click.
Actionable outputs
What you leave with
- Prioritized fixes: UI friction, async retries, and rate limits clearly scoped.
- A confidence map: the ranges of load and speed where loops hold steady.
- A short runbook: stages, vitals, endpoints, owners, and rollback steps for the next growth spike.