Ranking before rules: how a PM drove Airbnb’s safety shift
A story of how product signals, experiments, and layered enforcement can shift platform behavior when no one team owns the problem.
The crisis, and no single owner
After deadly house parties made headlines, safety moved from a values slide to a top problem. The issue cut across the product. Listings, guests, neighbors, and cities were part of it. The hard part was not words. It was changing behavior on the platform. No PM could ban parties alone. Policy could say the right thing, but it would not move ranking, search, or booking flows by itself.
- Start where you have a lever: signals and ranking, not only policy.
- Run small tests to build a trail of evidence.
- Turn safety goals into metrics and observable behaviors.
- Coordinate a sequence: educate, add friction, then sanction.
- Treat “temporary” changes as experiments that justify long-term rules.
Where I started: signals, not statements
I could not write a policy. I could adjust how the product saw risk. So I listed signals that hinted at party risk. Prior complaints on a listing. Clusters of noise reports around an area. Booking patterns that looked like parties. Host and guest history. I did not announce anything. I fed these signals into ranking. High-risk homes dropped in search. Safer options rose. That move cost nothing in press time and kept us inside the product code we already owned.
Build the evidence, then ask for power
Legal and ops wanted proof before tighter rules. Comms wanted to know what we could stand behind in public. I ran a small geography test. We picked a few cities. We tracked complaint rates, cancellation, and rebooking after we shifted ranking and added simple booking friction for high-risk cases. The point was not to be perfect. It was to gather clean, fast evidence.
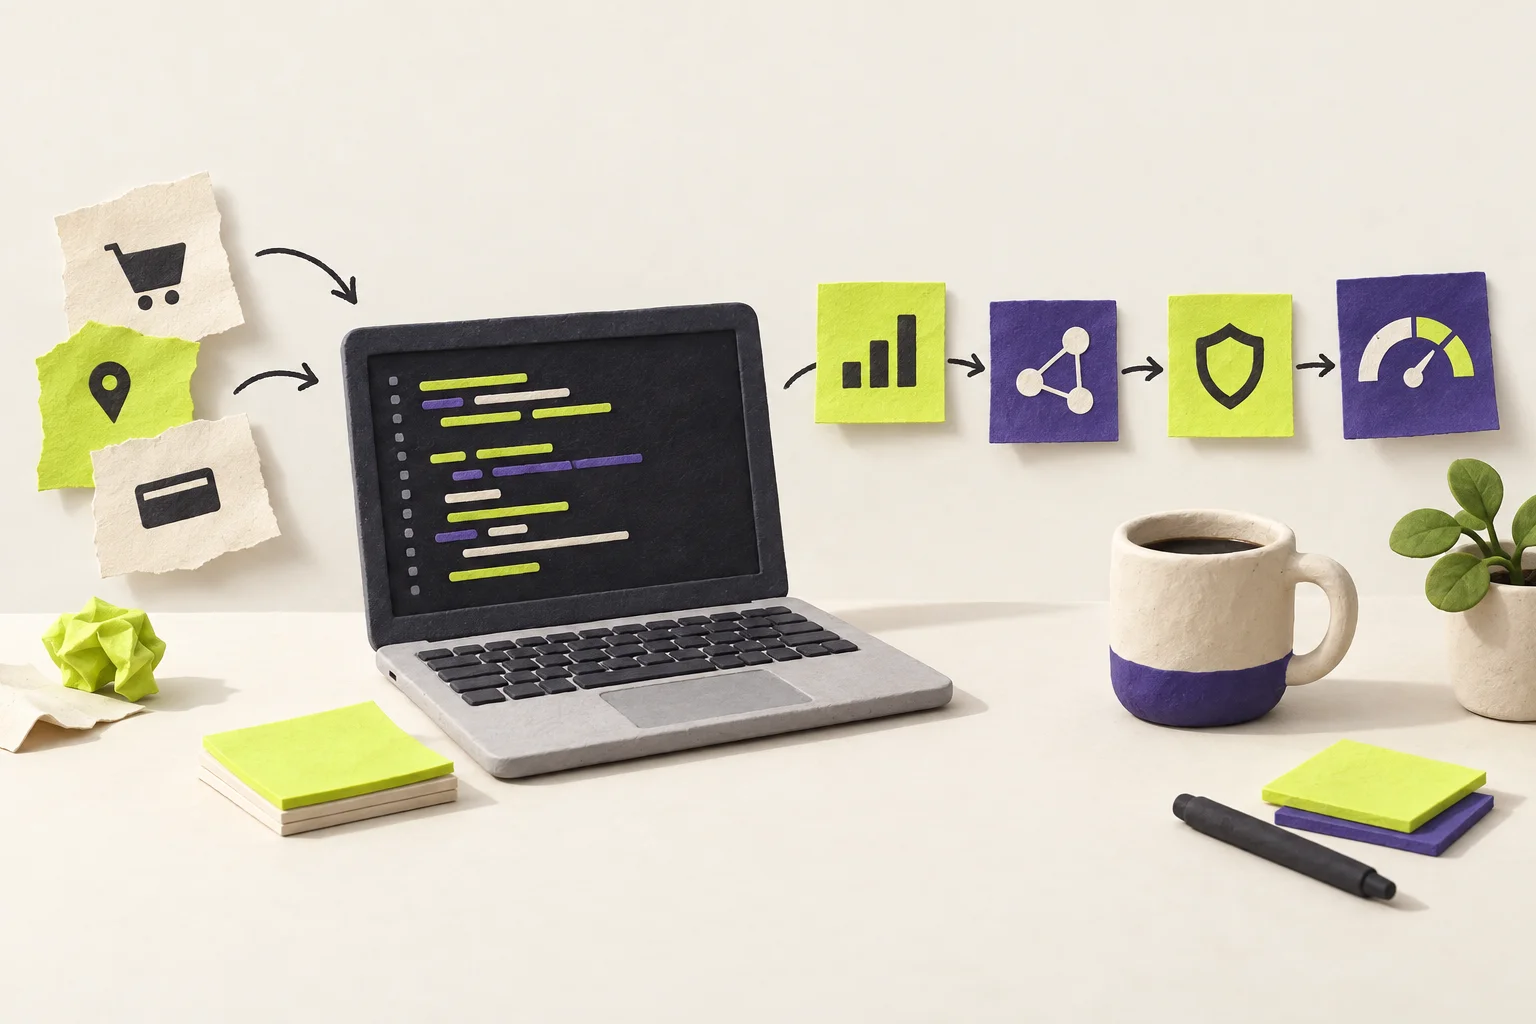
List what you can observe today: complaints, listing history, booking patterns, neighbor reports.
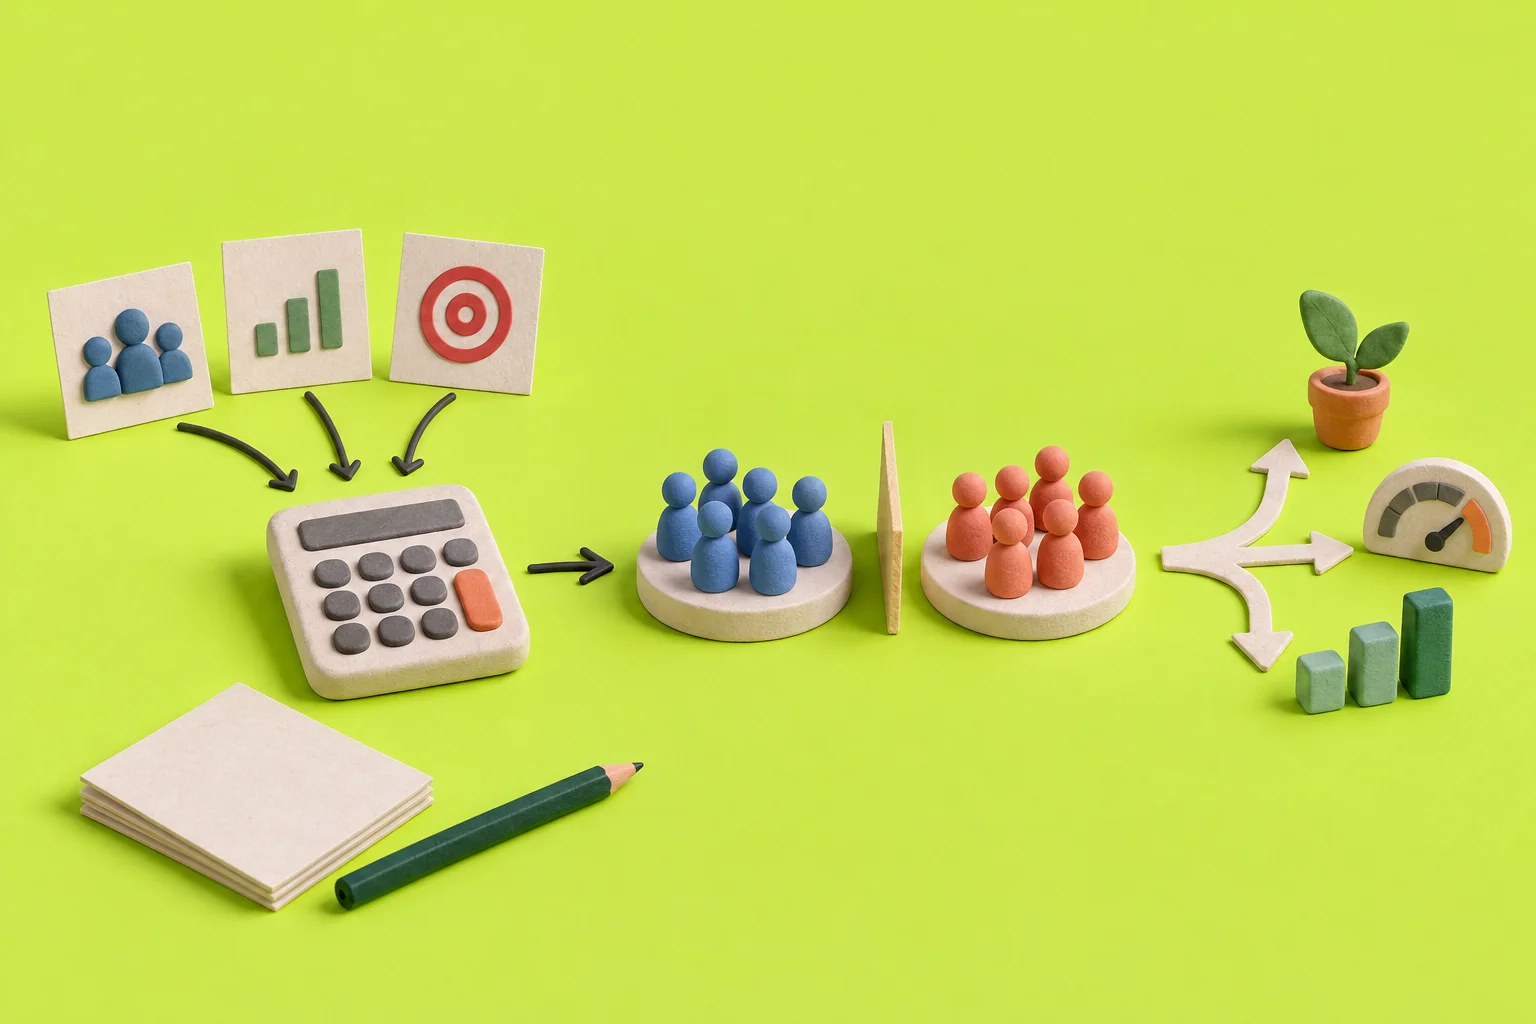
Combine signals into a simple risk score. Keep it auditable. Log inputs and outputs.
Pick one region. Apply the score to ranking and light booking friction. Timebox it.
Track complaint rate per booking, rebooking after blocked or downranked options, host churn.
Share a one-page brief of results with trust, legal, ops, and comms. Use a One-pager.
Make safety computable
We translated safety into inputs that engineers could ship. Examples: de-prioritize listings tied to recent complaints. Add friction when a booking matched a high-risk pattern. Nudge to rebook into lower-risk options nearby. Each rule had a clear metric and a log. That made trust and legal more comfortable. They could see cause and effect.
| Visible but weak | Evidence-driven and enforceable |
|---|---|
| Add a new warning screen. | Downrank risky listings and log the impact on complaints. |
| Publish a strict policy blog post. | Gate high-risk bookings with extra steps and track diversion. |
| Announce a blanket ban without data. | Run a geo test, then scale with documented results and playbooks. |
Layer the response, in public
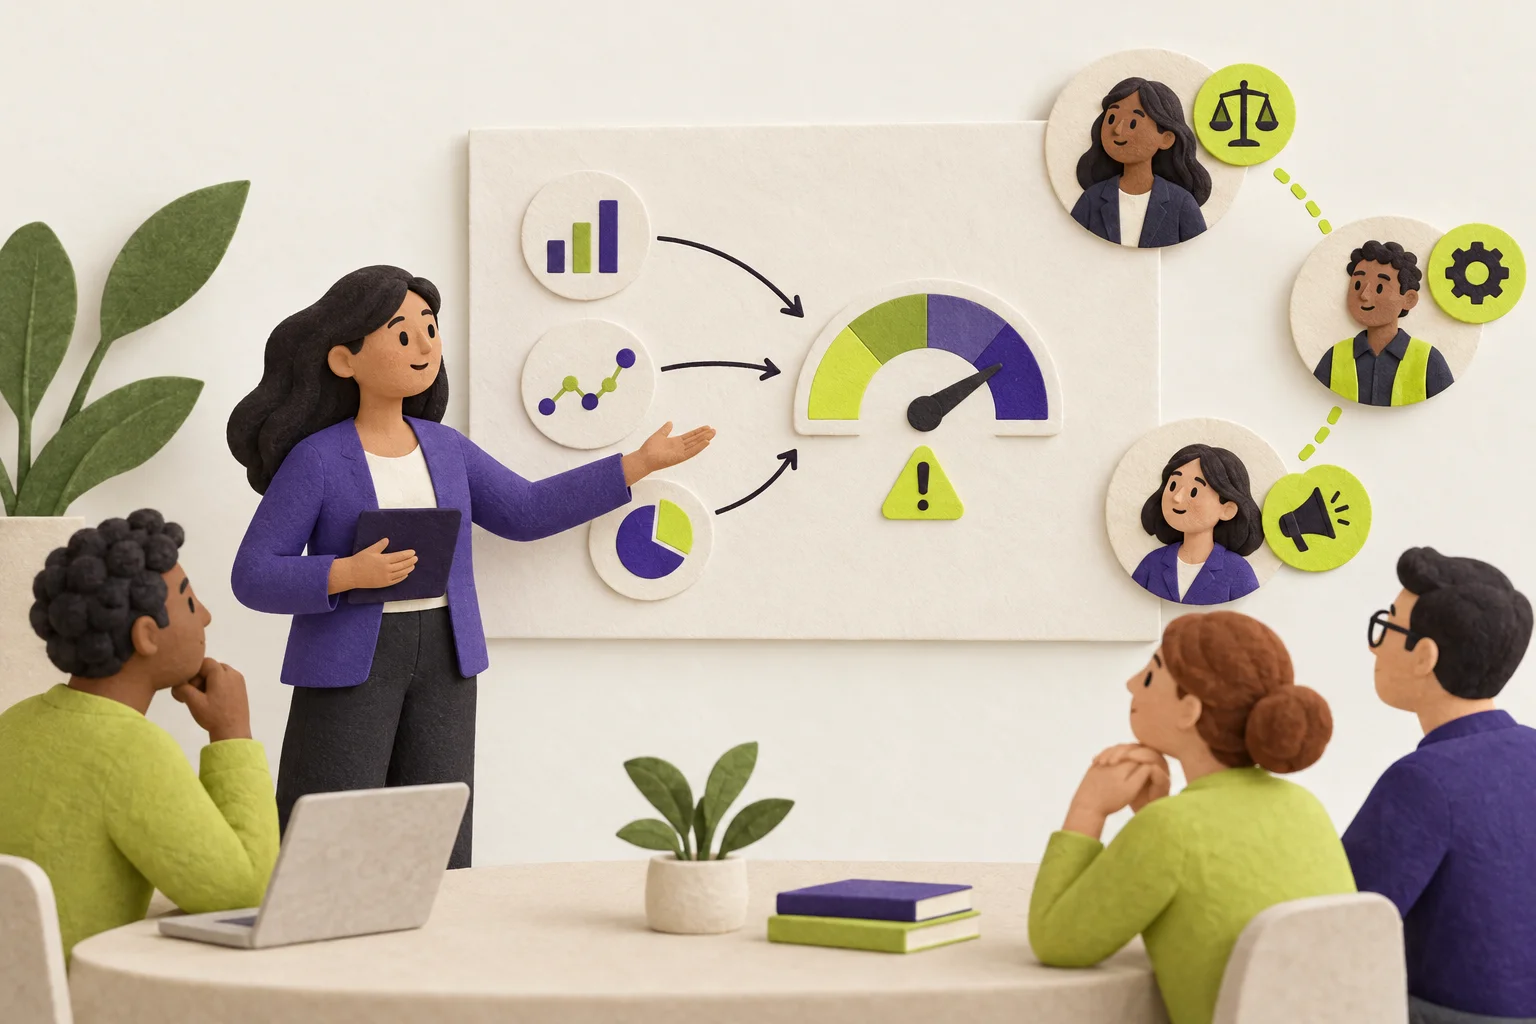
One big ban sounds strong. It fails if you cannot enforce it. We sequenced work across teams. First, education for guests and hosts. Clear do’s and don’ts in product and email. Next, friction in the flow for high-risk cases. Extra steps that made parties harder to book. Then, sanctions for repeat abuse, handled with trust and ops. Comms turned test results into simple public commitments. Policy codified what the product was already enforcing. Each layer had owners. I kept the order and the handoffs.
- Have metrics and logs for every safety change.
- Agree on thresholds with legal before wider rollout.
- Prepare host and support scripts with ops.
- Give comms one page of results, not claims.
Worked example: a listing risk score
We prototyped a score that ranged from low to high. Inputs were recent complaints, host history, location patterns, and booking context. We used it in two places: search ranking and inbox messaging to set expectations.
We ran it in one region for a few weeks. Success was a lower complaint rate per booking with stable rebooking after any diverted request. We also watched host churn and guest satisfaction. The score was auditable. Every decision traced back to inputs.
- Define inputs you can measure now. Keep the list short.
- Weight them with simple rules. No black box needed to start.
- Apply the score to downrank the top-risk slice only.
- Add a soft nudge in the inbox that points to safer options.
- Measure complaint rate, rebooking, and support contact rate.
- Freeze the model and share results with trust and legal.
- Decide on broader rollout and tighter enforcement based on data.
What it taught me
The urge to fix a moral wrong can push you to ship flashy UX changes. They rarely move outcomes. The better path is quiet at first. Change ranking. Add narrow friction. Measure. Then bring legal, ops, and comms the proof they need. Make a public promise you can keep, then layer enforcement. The point is simple: a PM can change product behavior without formal authority by starting with product levers, building evidence, and coordinating the sequence.
- Confusing urgency with rushing a visible but weak UI change.
- Skipping instrumentation that stakeholders need to justify action.
- Betting on a single big ban instead of layered controls you can enforce.