ED Triage for Product: Prioritise Under Pressure
Borrow emergency-department triage to sort P0–P4 work, set SLAs, run separate queues, and keep delivery moving under pressure.
This guide is for busy PMs who juggle bugs, customer escalations, roadmap bets, and scarce engineering time. By the end, you will have a five-level triage model, clear SLAs, separate queues, a short intake script, and a simple loop to run it live without slowing delivery.
Borrow emergency-department triage. Classify work by time to act, not who shouts. Run separate queues with owners and SLAs. Use a short intake script. Get a fast second opinion. Measure accuracy and adjust weekly.
Why borrow ED triage for product
In an emergency department, not every patient goes first. Teams sort by risk and time to action. Life-or-death cases jump the line. Routine cases wait. Each has a path, an owner, and a time target.
Product work under pressure is similar. Everything feels urgent. Stakeholders push. A single ranked backlog breaks. It creates context switch and noise. ED triage gives you a small set of levels, each with a clock and a lane. That frees engineering to deliver planned work while true emergencies move fast.
Triage sorts by time to act. Not by who shouts the loudest.
| Single ranked backlog | Triage with separate queues |
|---|---|
| One list, many voices compete | Few lanes, each with a clear purpose |
| Priority feels subjective | Objective intake questions map to levels |
| Owners change as items bubble up | Each lane has a fixed owner and rota |
| SLAs are unclear or ignored | Each lane has a time-to-action SLA |
| Frequent context switching | Planned work is protected from P0/P1 noise |
| Hard to measure decision quality | Track re-triage rate and SLA breaches |
The levels: copy the ED pattern
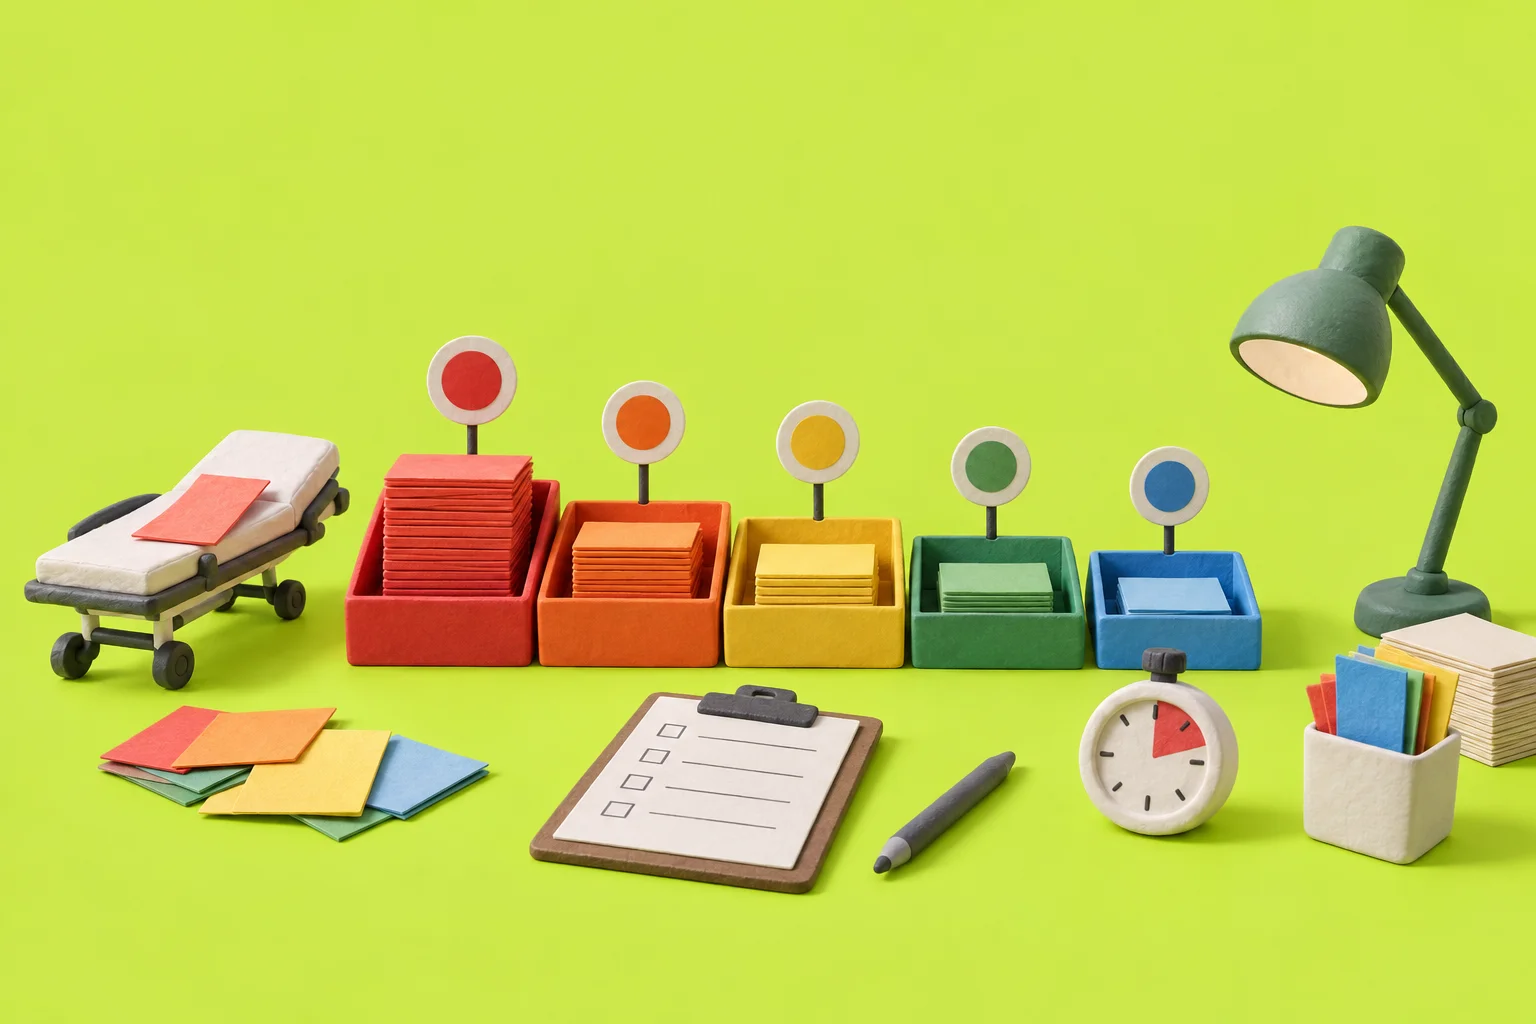
Use five levels. Keep names simple. Tie each to time-to-action and an owner.
- Resuscitate Act now. On-call stops everything.
- Urgent Act within hours. On-call routes and pairs.
- Urgent‑ish Act within a day. Squad handles next.
- Routine Act within days. Planned into sprint.
- Watch No action yet. Monitor and collect data.
Do not add more levels. Fewer is better under pressure.
Steps to set up triage in your team
Define levels and SLAs
Write five levels with clear examples and time-to-action. Name the owner for each lane. Publish in one page. Keep it short.
Build an intake script
Use objective questions that map to symptoms: data loss, payment failure, outage scope, core task blocked, workaround exists, user count, segment, first seen, repeat rate, last good state.
Create separate queues
Make one board per level. Set WIP limits and owners. Add SLA clocks to each board. No mixing levels in one queue.
Run a triage loop
Hold two short standups daily. Assign a rotating triage owner. New items get classified fast. Ambiguous cases get a quick pair review.
Add a second opinion
When in doubt, ask an engineer or support lead. Use a short rubric and decide within minutes. Document the reason.
Measure and tune weekly
Track re-triage rate, SLA breaches, and user impact after fix. Review the rules every week. Adjust examples and thresholds.
Protect delivery
Define what interrupts squads. Only P0 and P1 should. Everything else joins the right lane without breaking the plan.
Triage script: ask for symptoms, not opinions
Use a short script at intake. Keep it factual and fast.
- What broke? Pick from a list: data loss, payment failure, outage, core task blocked, minor UI, other.
- Scope: one user, many users, all users.
- Segment: paying, trial, internal.
- Workaround: yes or no. Describe if yes.
- When first seen? Has it happened before?
- Evidence: link to logs, steps to reproduce, order IDs, screenshots.
Map combinations to levels. For example, data loss with any scope is P0. Payment failure that blocks many users is P1. A core task broken with no workaround is P2. A feature bug with a clear workaround is P3. Ideas and small asks are P4.
Rollout checklist
- Write and share the five levels with SLAs and owners.
- Set up five queues with SLA timers and WIP limits.
- Create an intake form with the symptom questions.
- Start a rotating triage owner and an on-call rota.
- Schedule two daily triage standups.
- Add a fast second-opinion rule for edge cases.
- Publish a dashboard with SLA counters.
- Review metrics and tune rules every week.
Worked example: a five-level triage for B2B SaaS
Here is a simple model you can lift. It covers levels, SLAs, intake, on-call, and a dashboard.
Levels and SLAs
- P0 · 1h Data loss of any kind. Act within 1 hour. Owner: on-call engineer and PM. All hands if needed.
- P1 · 4h Billing failure or major outage. Many users blocked. Act within 4 hours. Owner: on-call engineer, SRE if relevant. PM coordinates comms.
- P2 · 24h Severe UX break for a core task with no safe workaround. Act within 24 hours. Owner: product squad on rotation.
- P3 · 5d Feature bug with a known workaround. Act within 5 working days. Owner: feature squad.
- P4 · backlog Nice-to-haves and ideas. No SLA to act. Review in roadmap sessions.
Intake form
- Reporter, account ID, product area.
- Symptom (pick list): data loss, billing failure, outage scope, core task blocked, minor UI, other.
- Scope: one user, many users, all users; segment: paying, trial.
- Workaround available: yes/no; steps to reproduce; last known good.
- Evidence links: logs, order IDs, error IDs.
On-call and ownership
- On-call engineer rotates weekly. They own P0/P1 with a clear playbook and paging rules.
- Triage owner rotates daily across PMs or leads. They classify intake, run standups, and chase blockers.
- Each squad owns P2–P3 for its area. P4 sits in the ideas backlog and is reviewed in roadmap forums.
Queues and boards
- Five boards: P0, P1, P2, P3, P4. Each with WIP limits and SLA timers shown on cards.
- P0/P1 are pull-only by on-call. P2/P3 are scheduled by squads. P4 has tags and themes for roadmap review.
How to run it live
- Two 10-minute triage standups daily. Morning: scan new intake and SLA risks. Afternoon: re-check breaches and reassign if needed.
- Forced reclassification at 48 hours for any open P2/P3. If it still hurts, move it up or close it with a documented reason.
- Weekly review board. Look at re-triage rate, SLA breaches, user impact after fixes, and any escalations. Tune rules and examples.
- Clear comms templates: status page notes for P1 outages, direct updates for P0 when data is at risk.
Dashboard
- Open count by level with SLA counters and flags for at-risk items.
- Re-triage rate week over week.
- SLA breaches by level and mean time to first action.
- Post-fix user impact: users unblocked, refunds prevented, support volume drop.
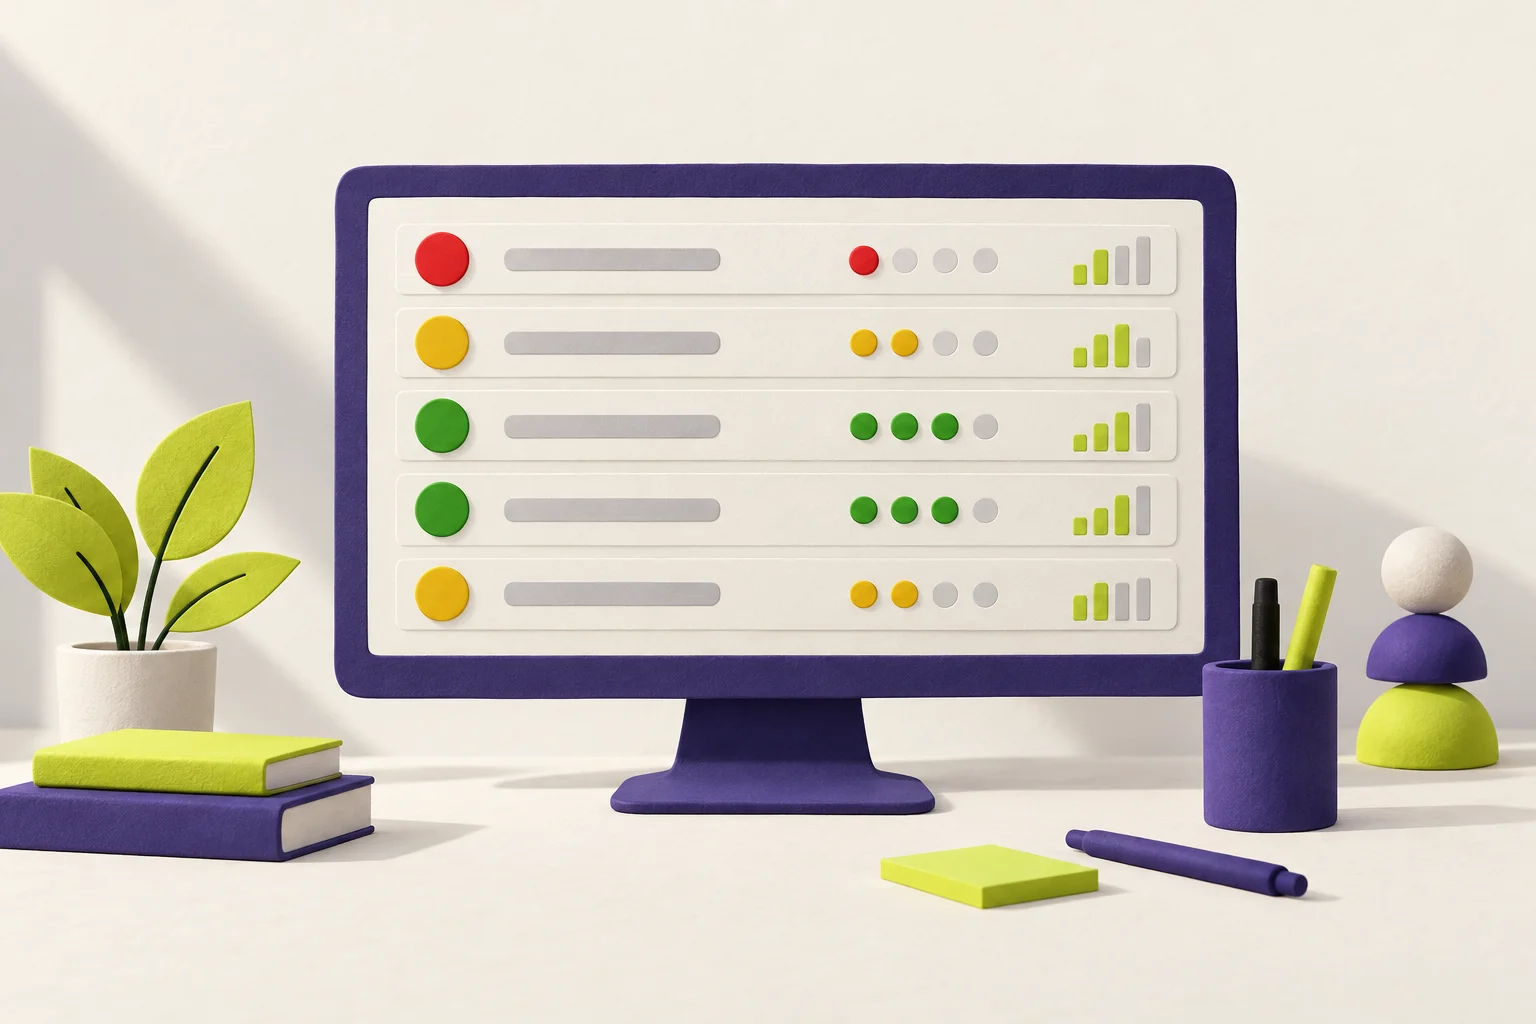
Objective decisions beat politics
Use rules, not opinions. The intake script ties symptoms to levels. The triage owner applies the rule, then seeks a second opinion if unsure. Keep a short rubric. Decide fast and move on.
Publish the rules where support, sales, and engineering can see them. Train new joiners with three example cases per level. Update examples weekly as patterns change.
Measure triage accuracy and iterate
Three signals tell you if triage works:
- Re-triage rate: how often items change level within 24–48 hours. You want this low.
- SLA breaches: count and trend by level. If breaches rise, adjust capacity or rules.
- User impact after fix: did the action reduce pain? Track unblocked users or support tickets.
Review these weekly. Adjust thresholds, examples, and owner load. Keep the five levels stable even as details shift.
Common mistakes to avoid
- Inflating urgency to win resources. Fix with objective symptoms and second opinions.
- Setting SLAs without capacity. Size the on-call rota and squad buffers first.
- Adding too many levels. Five is plenty.
- Skipping the second opinion. Bias creeps in fast under stress.
- Not measuring outcomes. Without data, rules drift and trust drops.
Once your levels and SLAs are set, map them into one prioritisation space so queues and SLA breaches are enforced automatically. You can do this with the PikoPM Prioritisation tool.